Reproducing Double Descent: Why 300 Features Beat 39 on the Same 40 Data Points
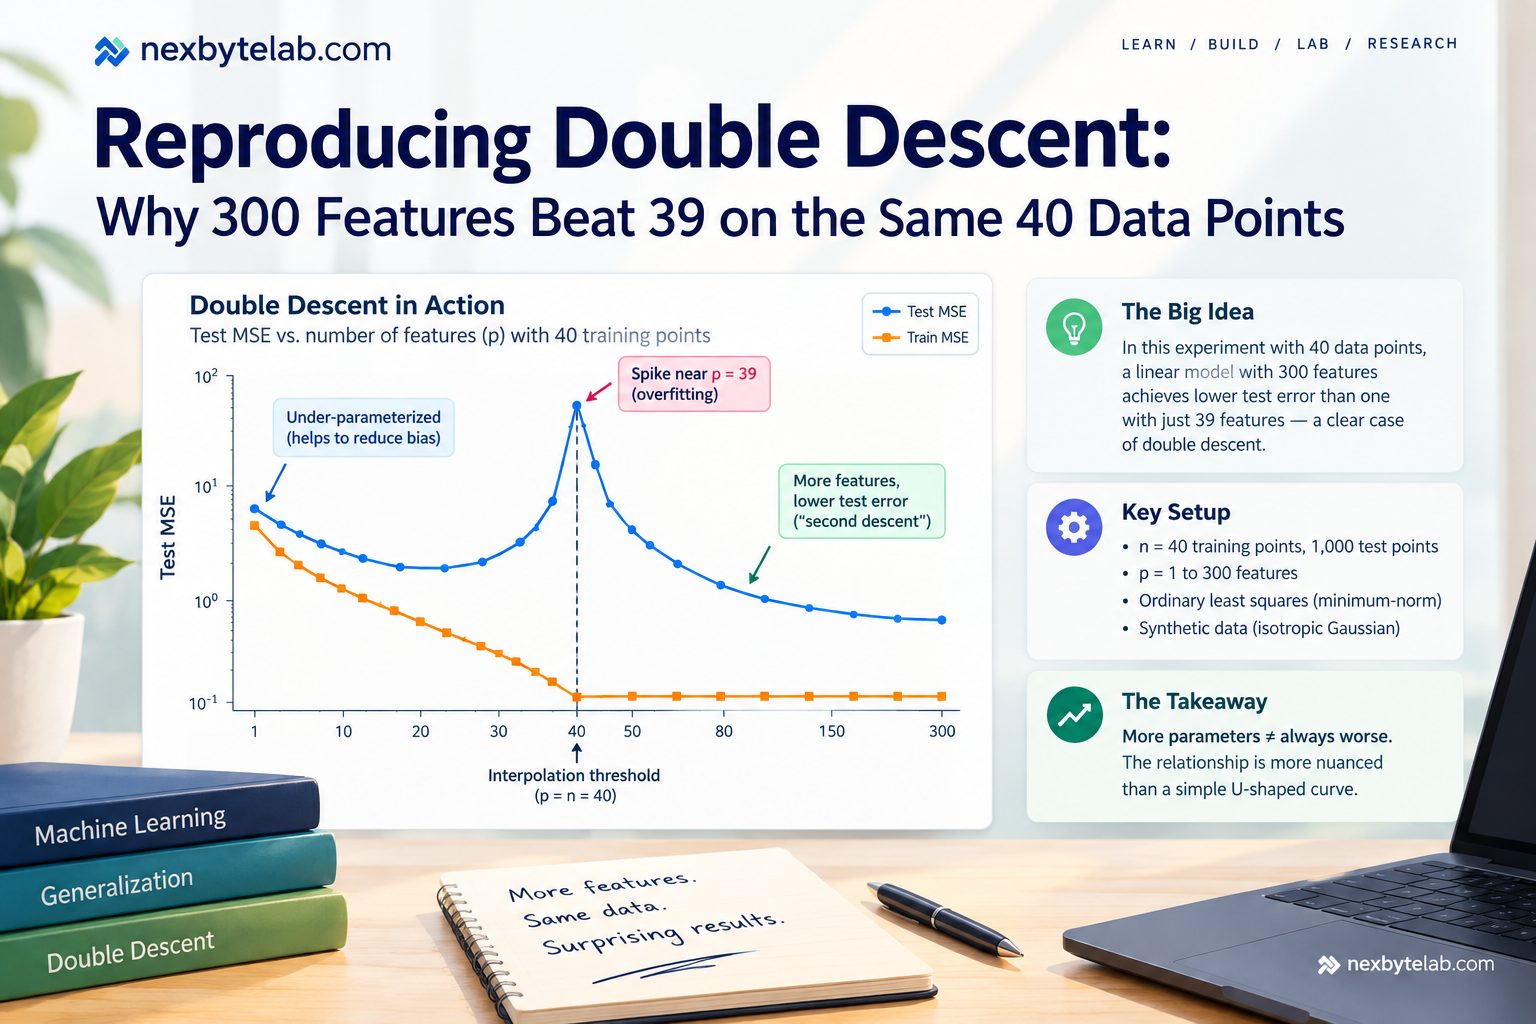
This double descent linear regression experiment reproduces the phenomenon in pure NumPy: test error spikes near the interpolation threshold, then falls again as features climb toward 300.
There is a familiar machine-learning story:
As a model becomes more complex, training error falls—but eventually the model overfits and test performance gets worse.
That gives us the textbook U-shaped bias–variance curve.
Too simple?
Underfitting.
Too complex?
Overfitting.
Somewhere in between lies the sweet spot.
That picture is useful.
But it is not the whole story.
In many modern machine-learning settings, something stranger can happen.
As model capacity increases, test error may:
- decrease,
- increase sharply near the point where the model can exactly fit the training data,
- and then decrease again as the model becomes even more overparameterised.
That second improvement is known as:
double descent.
I wanted to see whether this apparently counter-intuitive behaviour could be reproduced without:
- a neural network,
- a GPU,
- millions of samples,
- or a giant dataset.
So I built a deliberately small experiment:
40 training observations
and progressively increased the number of available features.
The surprising result was that a model using 300 features generalised better than one sitting close to the interpolation threshold at 39 features.
The goal of this article is not to claim that more parameters are always better.
It is to understand why the classical picture of overfitting becomes incomplete once we cross into the interpolating regime.
1. The Classical Picture
Suppose we increase model complexity.
At first, the model is too simple to capture the underlying pattern.
This is underfitting.
As complexity increases, test performance improves.
Eventually, however, the model begins fitting idiosyncrasies and noise in the training data.
Test error rises.
Conceptually:
underfitting → good fit → overfitting
This produces the familiar U-shaped test-error curve.
For decades, this has been an extremely useful mental model.
And in many problems, it remains useful.
But modern machine-learning models introduced a puzzle.
Very large neural networks often contain enough parameters to fit their training data essentially perfectly.
According to the simplest version of the classical story, pushing capacity further should make generalisation worse.
Yet in many settings, it does not.
2. Enter Double Descent
The modern double-descent picture extends the classical curve.
As model capacity increases:
Region 1 — Underparameterised
The model does not have enough capacity.
Training error remains above zero.
Increasing capacity can improve both training and test performance.
Region 2 — Interpolation threshold
The model becomes just powerful enough to fit the training data exactly or almost exactly.
Test error can become unstable or spike dramatically.
Region 3 — Overparameterised
The model contains more degrees of freedom than are needed to interpolate the training data.
Surprisingly, test error can decrease again.
Conceptually:
descent → peak → second descent
Hence:
double descent.
Belkin and colleagues helped formalise and popularise this modern framing in 2019, connecting classical statistical learning intuition with the behaviour observed in highly overparameterised machine-learning models [1].
The underlying ideas and related interpolation phenomena have a broader history, so it would be too strong to say that double descent was simply “first discovered” in that paper.
3. The Question
I wanted to ask a very small question:
Can we reproduce double-descent-like behaviour using a simple linear model?
No deep network.
No image dataset.
No huge compute budget.
Just:
- 40 training points,
- synthetic features,
- linear regression,
- and progressively increasing model dimension.
If double descent appears even here, then the phenomenon is clearly not exclusive to deep neural networks.
4. Experimental Design
Keep the number of training observations fixed:
n = 40
Now vary the number of features:
p
For example:
1, 2, 5, 10, 20, 30, 35, 38, 39, 40, 41, 45, 50, 75, 100, 150, 200, 300
The critical region is where:
p ≈ n
because that is where the model approaches the capacity required to interpolate the training observations.
With 40 training samples, the interesting region should therefore appear around:
p ≈ 40
subject to details such as intercept handling, matrix rank and the exact data-generating process.
5. Why 39 Features Matters
For a linear model with an intercept, 39 input features plus the intercept give approximately:
40 fitted coefficients
for:
40 training observations
That places the system near the interpolation threshold.
This is the regime where the fitted solution can become extremely sensitive to the particular training sample.
Small changes in the data can lead to large changes in the estimated coefficients.
That instability can produce poor test behaviour even while training error approaches zero.
So the question becomes:
What happens if we keep adding features after crossing that threshold?
Classical intuition might suggest:
even more overfitting
But the experiment gives us something more interesting to examine.
6. Generate the Data
The experiment uses synthetic data so that we can control:
- sample size,
- feature count,
- signal,
- noise,
- random seed.
Conceptually, the target follows a known data-generating process:
y = signal + noise
The first part of the feature space contains useful predictive structure.
As dimensionality increases, additional features expand the model’s capacity.
This allows us to study what happens as the ratio:
p / n
moves from:
p < n
through:
p ≈ n
and into:
p > n.
7. Fit the Same Model at Every Dimension
For each value of p:
- select the first p features,
- fit linear regression,
- calculate training error,
- calculate test error,
- record the result.
The algorithm remains the same.
Only model dimensionality changes.
Conceptually:
from sklearn.linear_model import LinearRegression
from sklearn.metrics import mean_squared_error

model = LinearRegression()

model.fit(
    X_train[:, :p],
    y_train
)

train_prediction = model.predict(
    X_train[:, :p]
)

test_prediction = model.predict(
    X_test[:, :p]
)

train_mse = mean_squared_error(
    y_train,
    train_prediction
)

test_mse = mean_squared_error(
    y_test,
    test_prediction
)
This is deliberately simple.
The interesting behaviour comes from changing model capacity relative to sample size.
8. What Happened
The resulting test-error curve did not follow a simple U shape.
Instead, the broad pattern was:
lower capacity
↓
improving test performance
↓
sharp deterioration near interpolation
↓
improving test performance again in the overparameterised regime
The most striking comparison was:
300 features generalised better than 39 features on the same 40 training observations.
That sounds wrong if we interpret model complexity only through the classical:
more parameters = more overfitting
story.
But the behaviour becomes more understandable once we examine what happens near interpolation.
9. Why the Interpolation Threshold Can Be Dangerous
Near the interpolation threshold, the design matrix can become poorly conditioned.
The fitted model may need very large coefficients to pass through every training observation.
Those large coefficients can amplify small changes in the input.
So we can obtain:
near-zero training error
while producing:
large test error.
This is an important reminder:
Perfectly fitting the training data tells us almost nothing by itself about generalisation.
Interpolation is a property of training fit.
Generalisation is about unseen data.
They are not the same thing.
10. Why Can Adding Even More Features Help?
Once:
p > n
the system becomes underdetermined.
There are many parameter vectors capable of fitting the training data.
Which solution gets selected now matters.
For ordinary least-squares problems solved through standard numerical procedures, the solution in an underdetermined setting is commonly the minimum-norm interpolating solution.
Instead of requiring one unstable parameter vector near the interpolation boundary, the fitted solution can distribute the prediction across a larger parameter space.
Under some data-generating conditions, this minimum-norm solution can generalise better as dimensionality increases beyond the interpolation threshold.
This is one mechanism associated with the second descent.
But it is important not to turn this into a universal rule.
Overparameterisation does not automatically improve generalisation.
The result depends on the data distribution, signal structure, noise, model, optimisation procedure and implicit or explicit regularisation.
11. Why 300 Can Beat 39
The headline comparison now becomes easier to understand.
Around 39 features
The model is close to the interpolation threshold.
It has just enough flexibility to fit the training observations extremely closely.
But the solution can be unstable.
Noise can strongly influence the fitted coefficients.
At 300 features
The model is far into the overparameterised regime.
There are many possible interpolating solutions.
The numerical solution selected by least squares can have different norm and stability properties.
Under the conditions used in this experiment, that solution generalised better than the near-threshold model.
So:
300 features did not win because “more features are always better.”
It won because the model was operating in a fundamentally different parameterisation regime.
12. Training Error Tells Only Half the Story
Plotting training error alone would hide the interesting part.
As capacity increases, training error generally falls.
Near and beyond interpolation it can become essentially zero.
If we looked only at training performance, we might conclude:
“Everything after the interpolation point is equally good.”
Test error tells a very different story.
The model can have:
almost zero training error
at both:
p = 39
and:
p = 300
while producing very different predictions on unseen data.
That is why generalisation must be measured on data that were not used to fit the model.
13. One Run Is Not Enough
A double-descent curve can be visually dramatic.
But a single random seed can exaggerate or suppress the effect.
So the stronger experiment repeats the procedure across multiple independent datasets.
For each feature count:
- generate a new training sample,
- generate a new test sample,
- fit the model,
- calculate test error,
- repeat across many seeds,
- report the distribution of test error.
The resulting plot should show:
mean test error
along with:
variability across runs.
This allows us to distinguish a systematic phenomenon from one unusually dramatic dataset.
14. The Interpolation Peak Can Be Highly Variable
There is another reason repeated runs matter.
Near interpolation, numerical instability can become severe.
Some training samples may produce moderate test error.
Others can produce enormous error.
That means the average near the interpolation threshold can be dominated by a relatively small number of catastrophic runs.
This is not merely a plotting inconvenience.
It is part of the phenomenon.
A useful analysis should therefore inspect:
- mean,
- median,
- standard deviation,
- quantiles,
- and individual extreme runs.
The mean alone may conceal what is happening.
15. Inspect the Worst Runs
Suppose the average test error spikes around:
p ≈ 39
The next question should be:
Is every run becoming moderately worse, or are a few runs becoming catastrophically bad?
Those are different phenomena.
Inspecting individual seeds can reveal whether the interpolation peak is driven by:
- systematic moderate instability,
- a handful of extreme solutions,
- or both.
This kind of forensic analysis is often more informative than simply plotting an average curve.
16. Condition Number and Numerical Instability
One useful diagnostic is the condition number of the design matrix.
A large condition number indicates that the system is sensitive to small perturbations.
Near interpolation, the design matrix can become poorly conditioned.
This means small changes in:
- observations,
- target noise,
- floating-point arithmetic,
can lead to large changes in fitted coefficients.
So a stronger version of this experiment should plot:
test error
alongside:
condition number
and perhaps:
coefficient norm.
If all three spike near interpolation, we have a much clearer picture of the mechanism.
17. Does This Contradict Bias–Variance Trade-Off?
Not exactly.
The classical bias–variance framework remains useful.
The problem is the overly simplified interpretation:
More model capacity must eventually mean monotonically worse generalisation.
Modern overparameterised systems reveal additional structure.
The behaviour depends not only on the number of parameters but also on:
- how solutions are selected,
- geometry of the feature space,
- optimisation,
- regularisation,
- signal-to-noise ratio,
- data distribution.
Double descent therefore extends our intuition rather than making classical statistics irrelevant.
18. Is Double Descent Universal?
No.
This is an important correction.
It would be too strong to say:
“Double descent is a general property of interpolating estimators.”
Double-descent behaviour has been observed and analysed across multiple model classes and experimental settings, including linear models, random features, kernel methods and neural networks.
But it does not necessarily appear in every dataset, every model or every training regime.
The shape and magnitude of the effect depend on the problem.
Some experiments show a dramatic interpolation peak.
Some show a mild one.
Some may show little obvious second descent over the capacity range examined.
So the appropriate statement is:
Double descent is an empirically and theoretically studied phenomenon that can occur in several overparameterised learning settings.
Not:
“Every interpolating model must exhibit double descent.”
19. What the Experiment Actually Shows
The experiment supports several useful conclusions.
1. Test error need not follow a simple U-shaped curve
Increasing capacity beyond interpolation can, under some conditions, improve generalisation again.
2. The interpolation threshold is special
The region around:
p ≈ n
can exhibit severe instability.
3. Zero training error does not determine test performance
Two interpolating models can generalise very differently.
4. Overparameterisation is not synonymous with poor generalisation
The relationship between capacity and generalisation is more complicated.
5. More parameters are not automatically better
The second descent is conditional, not universal.
20. What This Experiment Does NOT Show
This experiment does not prove:
“300 features are better than 39 features.”
It shows that they were better under this experimental setup.
It does not prove:
“More features always improve generalisation.”
They do not.
It does not prove:
“Overfitting no longer matters.”
It certainly does.
It does not prove:
“Classical statistics is wrong.”
It is not.
And it does not prove:
“Every overparameterised model exhibits double descent.”
The result is specific to the model, data-generating process, noise structure and fitting procedure used here.
21. Why This Matters for Modern Machine Learning
Modern neural networks routinely operate in regimes where:
number of parameters >> number of training observations
or, more generally, where model capacity is sufficient to interpolate the training data.
Yet many of these models generalise remarkably well.
Parameter count alone therefore cannot explain generalisation.
Researchers increasingly study additional factors such as:
- implicit regularisation,
- optimisation dynamics,
- margin,
- model geometry,
- data structure,
- effective complexity,
- minimum-norm solutions.
Double descent is one piece of that larger puzzle.
22. A Better Follow-Up Experiment
The natural next step is to test which ingredients make the double-descent curve appear or disappear.
For example, repeat the experiment while varying:
Noise level
low → medium → high
Does the interpolation peak become larger as target noise increases?
Training-set size
n = 20 → 40 → 80 → 160
Does the peak move with the interpolation threshold?
Regularisation
Compare:
ordinary least squares
with:
ridge regression
Does explicit regularisation smooth the interpolation peak?
Feature correlation
Compare:
independent features
with:
highly correlated features
How does conditioning change?
Signal sparsity
What happens when only a few features contain useful signal?
Those experiments would move us from merely reproducing double descent to investigating why and when it appears.
23. Add Ridge Regression
Perhaps the most interesting follow-up is regularisation.
Ordinary least squares asks us to minimise:
||y − Xβ||²
Ridge regression adds a penalty:
||y − Xβ||² + λ||β||²
where:
λ > 0
penalises large coefficient norms.
Since instability near interpolation can involve very large coefficients, ridge regularisation may dramatically change the curve.
This creates a useful experiment:
Does regularisation remove or soften the interpolation peak?
That question connects double descent directly back to classical statistical practice.
24. The Bigger Lesson
The most interesting part of this experiment is not that:
300 > 39
The interesting part is that model capacity changes the geometry of the learning problem.
Below interpolation:
the model cannot fit everything.
Near interpolation:
the model can just barely fit everything and may become extremely unstable.
Far beyond interpolation:
many solutions can fit everything, and the way the learning algorithm selects among them becomes critical.
That means simply counting parameters is not enough.
We also need to understand:
- which solution is selected,
- how stable that solution is,
- how the data are structured,
- and how the model behaves on unseen observations.
25. The Honest Interpretation
The dramatic version of this article would say:
“The bias–variance trade-off is wrong. More parameters make models better.”
That is not what the experiment demonstrates.
The more accurate conclusion is:
The simple U-shaped story is incomplete in some interpolating and overparameterised regimes.
Under the conditions tested here, test error became very large near the interpolation threshold and then declined again as dimensionality increased substantially beyond it.
That is double descent.
It does not invalidate classical statistics.
It tells us that modern high-capacity models can operate in regimes where our simplest intuitions about complexity need to be extended.
Conclusion
Forty training points.
Thirty-nine features.
Three hundred features.
Classical intuition might suggest that the 300-feature model should be the more dangerous one.
In this experiment, it was not.
The model near the interpolation threshold was substantially less stable, while moving further into the overparameterised regime improved generalisation.
That does not mean:
more parameters are always better.
It means:
the relationship between model capacity and generalisation can change once we cross the interpolation threshold.
The practical lesson is simple.
When evaluating model complexity, don’t ask only:
“How many parameters does the model have?”
Also ask:
Where is the model relative to interpolation, what solution does the learning algorithm select, and how does that solution perform on genuinely unseen data?
Sometimes the most unstable model is not the largest one.
It is the one sitting right at the boundary.
References and Further Reading
[1] Belkin, M., Hsu, D., Ma, S., & Mandal, S. (2019). Reconciling modern machine-learning practice and the classical bias–variance trade-off. Proceedings of the National Academy of Sciences, 116(32), 15849–15854.
A highly influential paper formalising the modern double-descent perspective.
https://doi.org/10.1073/pnas.1903070116
[2] Belkin, M., Hsu, D., & Xu, J. (2020). Two Models of Double Descent for Weak Features. SIAM Journal on Mathematics of Data Science, 2(4), 1167–1180.
Examines double descent in relatively simple models and helps connect the phenomenon to weak-feature settings.
https://doi.org/10.1137/20M1336072
[3] Hastie, T., Montanari, A., Rosset, S., & Tibshirani, R. J. (2022). Surprises in High-Dimensional Ridgeless Least Squares Interpolation. Annals of Statistics, 50(2), 949–986.
A detailed theoretical analysis of interpolation and generalisation in high-dimensional least-squares models.
https://doi.org/10.1214/21-AOS2133
[4] Nakkiran, P., Kaplun, G., Bansal, Y., Yang, T., Barak, B., & Sutskever, I. (2021). Deep Double Descent: Where Bigger Models and More Data Hurt. Journal of Statistical Mechanics: Theory and Experiment.
Explores double-descent behaviour in modern neural-network settings.
https://doi.org/10.1088/1742-5468/abc62c
[5] scikit-learn Documentation. LinearRegression.
Documentation for the ordinary least-squares implementation used in experiments of this type.
https://scikit-learn.org/stable/modules/generated/sklearn.linear_model.LinearRegression.html
Reproducibility and Interpretation Note
This article describes a controlled synthetic experiment with 40 training observations and progressively increasing feature dimensionality.
The headline comparison—300 features outperforming 39 features—is an empirical result from this particular experimental configuration. It should not be interpreted as evidence that adding features universally improves generalisation.
Double-descent behaviour has been observed and analysed across several model classes, but its presence, location and magnitude depend on the data-generating process, noise, model, optimisation procedure, regularisation and experimental design.
Claims about the interpolation peak should therefore be supported by repeated runs across random seeds, with variability reported alongside average test error.
Related Reading
- How Much Real Data Stops Model Collapse? A Minimal Recursive-Training Simulation — another controlled, reproducible experiment that overturns a piece of ML folklore
- Honest Write-Up: The Law of Large Numbers Doesn’t Always Save You — a companion look at when a classic statistical guarantee stops holding
- More Data, Worse Model: Reproducing Sample-Wise Double Descent at n = d — the sample-wise companion to this experiment, sweeping training-set size instead of parameter count