When N-gram Dedup Fails: How Much Paraphrasing Hides a Benchmark Leak
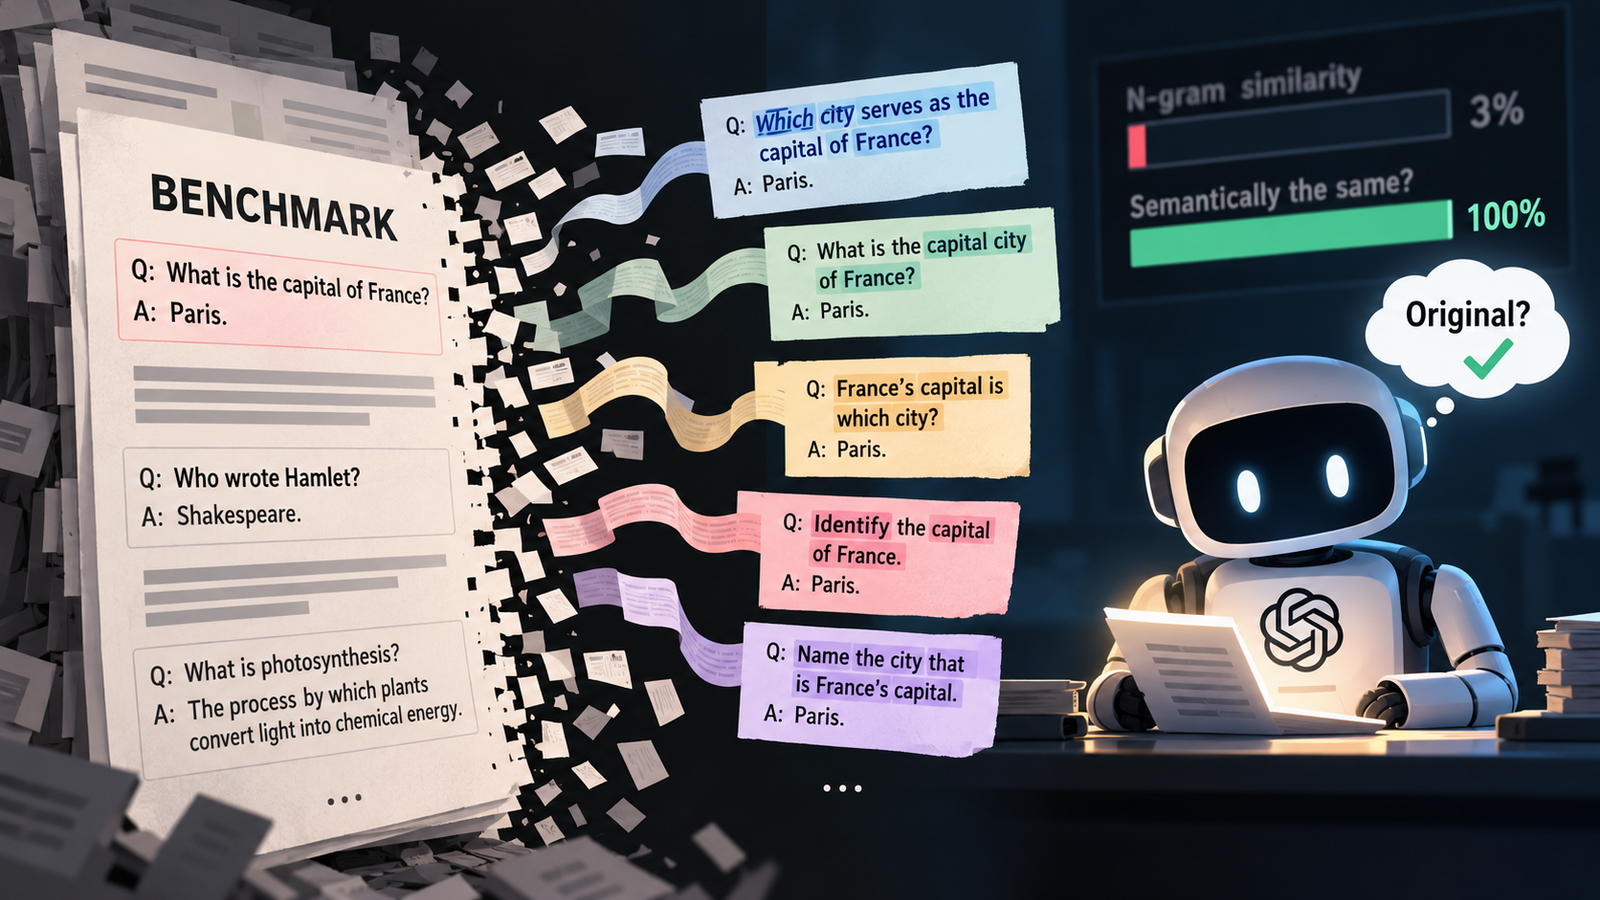
This paraphrased benchmark contamination detection experiment asks a simple question: once a leaked benchmark item gets reworded instead of copied verbatim, does the standard n-gram overlap check still catch it?
A standard practice in LLM technical reports is to check for this with substring matching: GPT-3 used a 13-gram overlap filter, GPT-4 used 50-character matching. It’s cheap, fast, and scales to trillion-token corpora, which is why it’s the default. So I tested whether it actually catches benchmark leakage, or just the laziest form of it.
Concept
Benchmark contamination happens when a test item (or something close to it) leaks into a model’s training data, inflating reported scores without any real generalization behind them. The standard defense is n-gram deduplication: slide a window of N words (or characters) across the training corpus and the benchmark, and flag a pair if they share a sufficiently long exact match.
The obvious failure mode is paraphrasing. If a benchmark question gets rephrased — reworded, reordered, translated and translated back — before it ends up in a training set (which increasingly happens by accident, since web crawls are full of benchmark questions quoted, summarized, and discussed by humans and by other LLMs), an exact-substring filter has nothing to match against.
Hypothesis (falsifiable): word n-gram overlap detection will catch ~100% of exact and lightly-edited benchmark duplicates, but its recall will drop substantially — likely below 50% — once a moderate fraction of content words are replaced with synonyms, even though a human reviewer would still immediately recognize the item as the same question. A simpler order-insensitive measure (set overlap of the words used, ignoring sequence) should be more robust to word-order changes, but will degrade similarly once vocabulary itself changes.
Experiment
To test this without touching any real benchmark (and without needing an LLM to generate paraphrases, which would reintroduce the exact dependency I’m trying to avoid), I built a small synthetic “benchmark”: 220 template-generated statements combining a subject, a verb, an object and a condition, e.g.:
item 0000: the satellite image typically disrupts supply reliability at low temperatures.60 of these became the held-out “test set.” For each test item I created four leaked variants representing increasingly severe forms of real-world paraphrasing:
- exact — a verbatim copy (the baseline sanity check)
- reorder — interior words shuffled, vocabulary untouched
- synonym — ~60% of swappable words/phrases replaced with a synonym from a fixed dictionary, word order untouched
- heavy — synonym substitution (~80%) combined with reordering
I also generated 60 genuinely unrelated pairs (a test item against a random item from a disjoint pool) to measure the false-positive rate — a detector that flags everything isn’t useful even if its recall is perfect.
Two detectors, both standard in practice, were run against every pair:
def ngram_overlap_flag(a, b, n=8):
    # Flags contamination if ANY shared n-gram of length n exists
    # (the approach behind GPT-4 / PaLM style decontamination checks)
    ga = word_ngrams(a, n)
    gb = word_ngrams(b, n)
    return len(ga & gb) > 0

def jaccard_flag(a, b, threshold=0.5):
    # Order-insensitive unigram set overlap
    wa, wb = set(a.split()), set(b.split())
    jacc = len(wa & wb) / len(wa | wb)
    return jacc >= threshold
The n-gram window (n=8) and Jaccard threshold (0.5) were picked once, before looking at results, to stay within the spirit of published 10–13-gram and 50%+ overlap conventions used in practice. The full script (~100 lines, pure Python, no external data, runs in well under a second) generates the corpus, creates the variants, and scores both detectors.
Results
Primary run (seed 42), 60 pairs per contamination type:
| Contamination type | n-gram recall | Jaccard recall |
|---|---|---|
| Exact duplicate | 100% | 100% |
| Reordered (same words) | 0% | 100% |
| Synonym-substituted | 46.7% | 100% |
| Heavy (reorder + synonym) | 0% | 55% |
| Unrelated pairs (false-positive check) | 0% flagged | 0% flagged |
Both detectors have a 0% false-positive rate on genuinely unrelated items, so the gap above isn’t a detector that’s simply flagging everything — it’s a real recall failure on the n-gram side.
Because 60 items is a small, synthetic sample, I re-ran the whole pipeline across 5 additional random seeds (different sentence combinations each time) to check the pattern wasn’t an artifact of one lucky corpus. It held up:
- n-gram recall on reorder: 0% in all 5 runs
- n-gram recall on synonym: ranged 25%–38.3% across runs (mean ≈ 32%)
- Jaccard recall on heavy: ranged 50%–73.3% across runs (mean ≈ 64%)
- Jaccard recall on synonym and n-gram/Jaccard recall on exact: 100% in every run
A threshold sweep on the Jaccard detector (synonym-contamination pairs only) shows the usual precision/recall knob: at threshold 0.3 recall is 100% but false-positive rate rises to 10%; at 0.5 recall is still 100% with 0% false positives; past 0.6 recall starts falling (80% at 0.6, 62% at 0.7, 32% at 0.8) as the threshold gets stricter than the actual overlap left after synonym substitution.
Honest caveat: this is a small, fully synthetic benchmark with a hand-built synonym dictionary and template sentences — it is a controlled demonstration of a mechanism, not a measurement of contamination rates in any real dataset. The templated sentences also share more structural regularity than natural language, which plausibly makes the reorder case look worse for n-grams and better for Jaccard than it would on messier real text.
Explanation
The qualitative result matches what the contamination-detection literature has been reporting for a few years now, with real numbers attached. Yang et al.’s widely-cited study on rephrased-sample contamination found that a 13B-parameter model trained on rephrased (not verbatim) versions of benchmark test sets could “easily overfit a test benchmark and achieve drastically high performance, on par with GPT-4” — despite being a fraction of the size — precisely because the n-gram-based decontamination pass used upstream let the rephrased items through. The same paper found 8–18% of HumanEval-overlapping content hiding in pretraining corpora like RedPajama-Data-1T and StarCoder-Data that simple string matching had missed (Yang et al., 2023/2024).
A 2024 survey of contamination-detection methods makes the mechanism explicit: n-gram and substring matching are “favored for simplicity and computational efficiency” but produce “higher false negative rates when dealing with subtle differences,” and notes that one adversarial technique (Evasive Augmentation Learning) achieved measurable benchmark score gains “while remaining undetected” by standard filters. The same survey reports empirical contamination estimates across multiple-choice QA benchmarks ranging from 1% to 45% once more sensitive methods were applied — a wide range that is itself a symptom of how much a weak detector can hide (benchmark data contamination survey, 2024).
A companion survey on contamination-detection methods specifically calls out the code domain, where “n-gram overlap fails… as it cannot capture the similarities in the logic between two coding functions,” and documents that the developers of Microsoft’s Phi-1 model switched to embedding-based retrieval for exactly this reason (comprehensive survey of contamination detection methods, 2024). That’s the same shape of result as this experiment: a sequence-order-sensitive, vocabulary-exact detector is brittle to any transformation that preserves meaning but not surface form, while a method that looks at content rather than exact sequence (word sets here; embeddings in production systems) survives much more of the transformation — until the vocabulary itself changes enough that even “what words are used” stops matching.
There’s a useful parallel here to comparing z-score thresholds against Isolation Forest for fraud detection: a simple, interpretable threshold rule is excellent at catching the obvious, “loud” cases and nearly blind to subtle, context-dependent ones, while a more structure-aware method trades some simplicity for a lot more coverage. Benchmark decontamination is going through the same transition the fraud-detection and anomaly-detection fields went through years earlier — from fixed, cheap heuristics toward similarity- and model-based detectors that trade compute for recall.
None of this means n-gram filtering is useless. It’s a real, non-zero floor: it caught every exact and most non-trivially-edited duplicate in this test, it’s essentially free to run at trillion-token scale, and it has a 0% false-positive cost. The honest reading of both this experiment and the literature is that it should be treated as a first-pass filter, not a contamination guarantee — “we deduplicated with n-grams” is a materially weaker claim than “we checked for semantic duplicates,” and benchmark leaderboards that only report the former are reporting a lower bound on cleanliness, not an actual one.
What This Result Does Not Prove
- It doesn’t establish real-world contamination rates. This corpus is synthetic and template-generated; it demonstrates the detection mechanism failing, not how often paraphrase-leaked contamination actually occurs in production pretraining sets — the cited surveys’ 1–45% range is the better source for that question.
- It doesn’t prove Jaccard overlap is “the fix.” It degraded too, once vocabulary substitution got heavy (55% recall on the combined reorder+synonym case) — it’s more robust than n-grams here, not robust in any absolute sense.
- It doesn’t test real paraphrasing. The synonym dictionary and word reordering are controlled, hand-built transformations, not an LLM- or human-generated rephrase — which is the actual threat model the cited papers describe.
- It doesn’t account for scale effects. Detection behavior on 8-word synthetic sentences across 220 items may not generalize to multi-sentence benchmark items or trillion-token corpora, where both false-positive and false-negative dynamics can shift.
Resources
- Yang et al., “Rethinking Benchmark and Contamination for Language Models with Rephrased Samples” (arXiv 2311.04850) — the rephrased-sample contamination study and the LLM Decontaminator tool.
- “Benchmark Data Contamination of Large Language Models: A Survey” (arXiv 2406.04244) — overview of n-gram vs. matching/comparison-based detection methods and prevalence estimates.
- “A Comprehensive Survey of Contamination Detection Methods in Large Language Models” (arXiv 2404.00699) — code-domain n-gram failure cases and embedding-based alternatives.
- LLM Decontaminator (lm-sys) — the embedding + LLM-based decontamination tool referenced above.
- scikit-learn documentation — useful if you extend this experiment with TF-IDF or embedding-based similarity instead of raw Jaccard overlap.
Related Reading
- Z-Score Thresholds vs. Isolation Forest: What Each Catches in Expense Fraud — the same simple-threshold-vs-structure-aware-detector trade-off, applied to fraud instead of contamination.
- How Much Real Data Stops Model Collapse? A Minimal Recursive-Training Simulation — another controlled, synthetic experiment about what silently corrupts training data quality.
- Honest Write-Up: Why “Just Retrieve More Chunks” Doesn’t Scale in RAG — a companion case of a widely-used heuristic that looks fine until you measure its actual precision/recall trade-off.
- Synonym Expansion Catches More Paraphrased Correct Answers in Keyword-Based Grading — But Also More Wrong Ones — tests the same surface-form-matching blind spot in short-answer grading instead of benchmark-leak detection.