Honest Write-Up: The Law of Large Numbers Doesn’t Always Save You
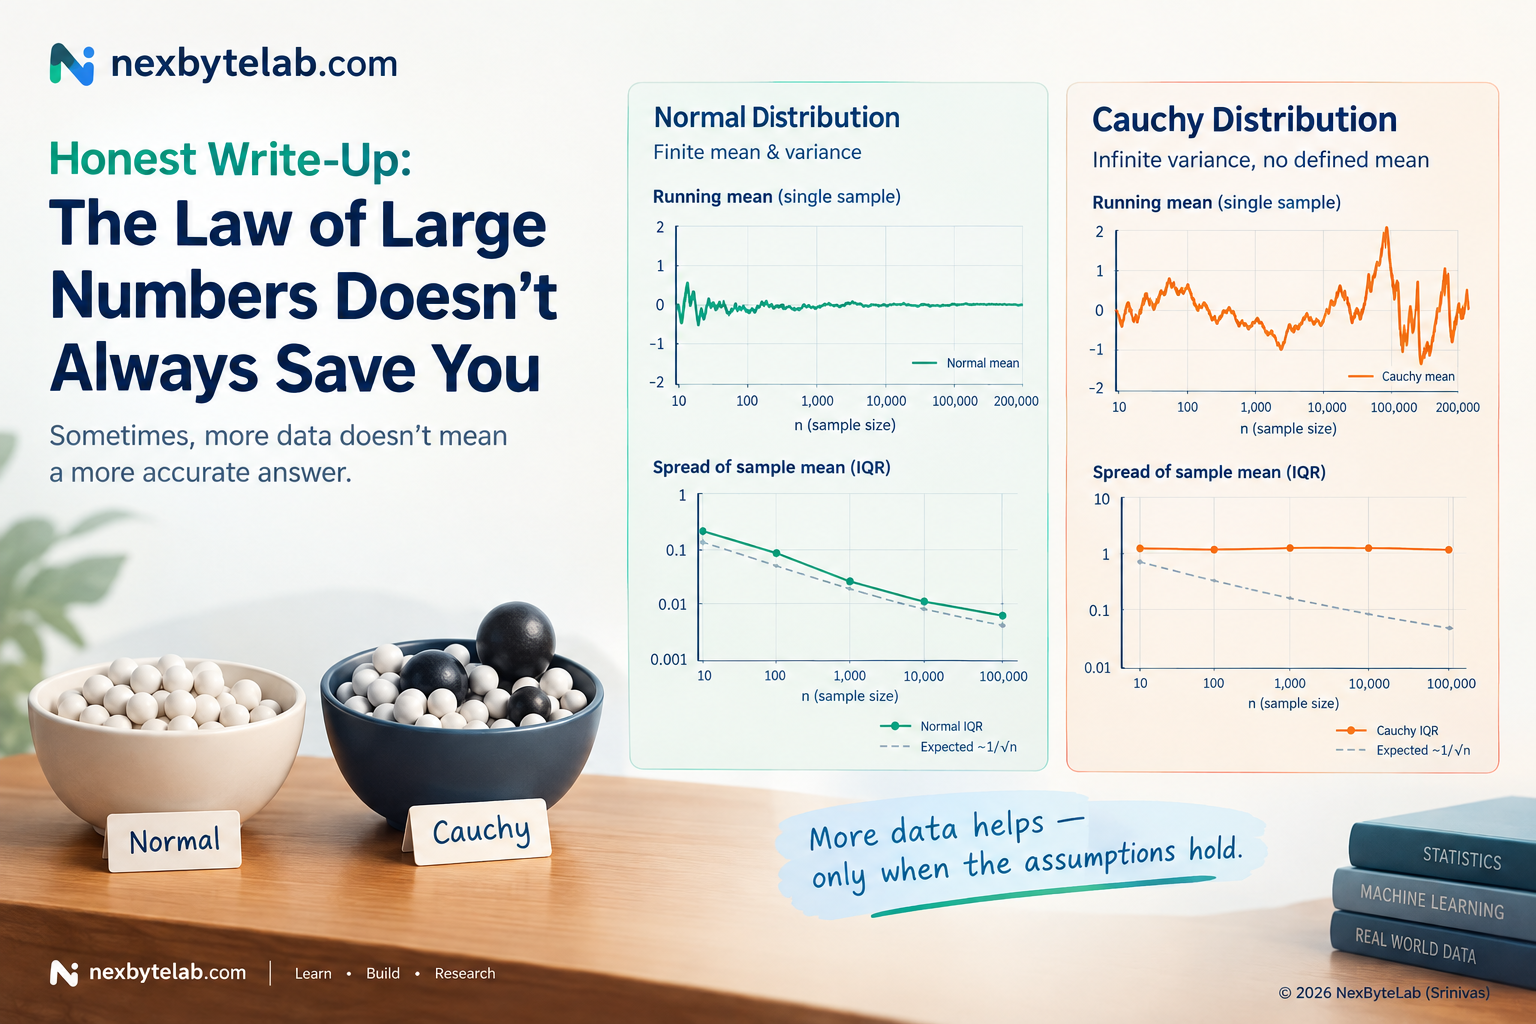
This law of large numbers failure shows up only once the data has fat tails: the sample mean never settles down, no matter how many observations you add.
One of the most reassuring ideas in statistics is that collecting more data should make an estimate more reliable.
Take enough observations, calculate their average, and the noise should begin to cancel out.
That intuition is backed by one of probability theory’s foundational results: the Law of Large Numbers.
But there is an important condition hidden inside that intuition:
The quantity we are trying to estimate must satisfy the assumptions required by the theorem.
What happens when it does not?
I wanted to see this directly rather than simply repeat the theorem.
So I ran a deliberately simple simulation.
First, draw increasingly large samples from a Normal distribution and watch the sample mean stabilise.
Then repeat exactly the same idea using a Cauchy distribution.
The result is a useful reminder:
More data does not automatically rescue an estimator when the mathematical assumptions supporting its convergence are absent.
And importantly, the Law of Large Numbers has not failed.
We asked it to operate outside the conditions of the standard version of the theorem.
The Question
Suppose we repeatedly estimate the centre of a distribution using the sample mean:
X̄ₙ = (X₁ + X₂ + … + Xₙ) / n
As the sample size n grows, should the sample mean become increasingly stable?
For many familiar distributions, yes.
But is that guaranteed for every probability distribution?
That is what this experiment tests.
1. The Familiar Case
Start with a standard Normal distribution:
X ~ N(0, 1)
Its population mean is:
E[X] = 0
Its variance is:
Var(X) = 1
Now generate observations:
X₁, X₂, X₃, ...
and calculate the running sample mean:
X̄ₙ = (1/n) Σ Xᵢ
At first, the estimate may move around considerably.
With five observations, randomness dominates.
With 50 observations, it usually becomes more stable.
With 5,000 observations, it should typically be much closer to zero.
That behaviour matches our everyday intuition about averaging.
2. The Law of Large Numbers
One common form of the Weak Law of Large Numbers says that, under appropriate conditions, the sample mean converges in probability to the population mean.
Informally:
X̄ₙ → μ as n → ∞
where:
μ = E[X]
For independent and identically distributed random variables, a standard form of the Law of Large Numbers assumes that the expected value exists and is finite.
Under those conditions, increasing the sample size makes the sample mean increasingly concentrated around the population mean.
The important phrase is:
under those conditions
The theorem is not simply:
“Average enough numbers and you will always discover the truth.”
3. The First Experiment: Normal Data
The first experiment is straightforward.
Generate observations from:
N(0,1)
Then calculate the running mean after:
- 10 observations,
- 100 observations,
- 1,000 observations,
- 10,000 observations,
- and beyond.
A simple implementation looks like this:
import numpy as np

rng = np.random.default_rng(42)

n = 100_000

x = rng.normal(
    loc=0,
    scale=1,
    size=n
)

running_mean = (
    np.cumsum(x)
    / np.arange(1, n + 1)
)
Plot:
sample size
against:
running sample mean
and the pattern is usually reassuring.
Early estimates fluctuate.
As more observations arrive, the running mean tends to settle near:
0
This is exactly the behaviour we expected.
4. Now Change Only the Distribution
Next, repeat the experiment using a standard Cauchy distribution.
rng = np.random.default_rng(42)

x = rng.standard_cauchy(
    size=n
)

running_mean = (
    np.cumsum(x)
    / np.arange(1, n + 1)
)
At first glance, the Cauchy distribution can look surprisingly ordinary.
It is:
- continuous,
- symmetric,
- centred visually around zero,
- bell-shaped.
But its tails are much heavier than those of a Normal distribution.
Very large observations are far more likely.
And mathematically, something crucial changes:
The standard Cauchy distribution does not have a finite expected value.
Its conventional population mean is undefined.
That changes everything about using the sample mean as an estimator of a population mean.
5. What Happens to the Running Mean?
With Normal data, the running mean tends to become increasingly stable.
With Cauchy data, something very different can happen.
The running mean may appear to settle for a while.
Then one extreme observation arrives.
The average jumps.
More observations arrive.
It appears to stabilise again.
Then another extreme observation moves it somewhere else.
Conceptually:
0.12
0.08
0.04
0.02
0.01
looks reassuring.
Then an extreme observation enters the sample.
Suddenly:
1.73
or:
-2.41
or some other large movement.
More data can smooth that disturbance temporarily.
But another sufficiently extreme observation can disrupt the running mean again.
The sample mean does not settle around a finite population mean because there is no finite population mean for it to converge to in the usual sense.
6. The Law of Large Numbers Did Not Fail
This is the most important correction to the way this experiment is sometimes described.
It would be tempting to say:
“The Law of Large Numbers fails for the Cauchy distribution.”
That wording is misleading.
A theorem is an implication:
If its assumptions hold, then its conclusion follows.
For the familiar iid Law of Large Numbers applied to sample means, the required finite expectation condition is not satisfied by the Cauchy distribution.
Therefore, the theorem has not been contradicted.
The more accurate statement is:
The standard Law of Large Numbers for iid sample means does not give us convergence to a finite population mean here because the Cauchy distribution does not have such a mean.
That distinction may sound technical.
It is actually the main lesson of the experiment.
7. Why the Cauchy Mean Does Not Exist
The standard Cauchy probability density is:
f(x) = 1 / [π(1 + x²)]
It is symmetric around zero.
That symmetry can make it tempting to say:
“Surely the mean must be zero.”
But calculating an expectation requires the relevant integral to be well-defined.
For the Cauchy distribution, the positive and negative contributions do not converge absolutely in the way required for an ordinary finite expectation.
So:
E[X]
is undefined.
Zero is the median.
Zero is also the mode.
But zero is not a finite expected value of the standard Cauchy distribution.
That distinction is crucial.
8. Heavy Tails Change the Game
The difference becomes easier to understand by comparing tail behaviour.
The Normal distribution assigns extremely small probability to observations far from its centre.
The Cauchy distribution’s tails decay much more slowly.
That means extremely large values remain sufficiently plausible to keep influencing the sample mean even when the sample is already large.
This is why statements such as:
“Outliers matter less when you have enough data”
need qualification.
That may be a useful intuition under some distributions.
It is not a universal statistical law.
9. An Even Stranger Property of the Cauchy Distribution
There is a particularly striking fact.
If:
X₁, X₂, …, Xₙ
are independent standard Cauchy random variables, then their sample mean:
(X₁ + X₂ + … + Xₙ) / n
is itself standard Cauchy distributed.
In other words:
Averaging more independent standard Cauchy observations does not make the distribution of the sample mean increasingly concentrated around zero.
For Normal data, averaging dramatically reduces the variability of the sample mean.
For standard Cauchy data, the sample mean retains the same Cauchy distribution.
That is why simply increasing n does not rescue the sample mean here.
10. Repeat the Experiment Across Many Seeds
A single simulation trajectory can be misleading.
Perhaps we simply encountered an unusually dramatic random sequence.
So a stronger experiment repeats the simulation using many random seeds.
For example:
seeds = range(100)

final_normal_means = []
final_cauchy_means = []

for seed in seeds:

    rng = np.random.default_rng(seed)

    normal_sample = rng.normal(
        0,
        1,
        size=100_000
    )

    cauchy_sample = rng.standard_cauchy(
        size=100_000
    )

    final_normal_means.append(
        normal_sample.mean()
    )

    final_cauchy_means.append(
        cauchy_sample.mean()
    )
Now compare the distribution of final sample means.
For Normal samples, the estimates should cluster increasingly tightly around zero as sample size grows.
For Cauchy samples, the sample means do not concentrate in the same way.
This turns the demonstration from one dramatic line on a chart into a reproducible comparison across repeated runs.
11. Sample Size Is Not a Substitute for Assumptions
This experiment illustrates a broader mistake in data science.
We often hear:
“The dataset is huge, so the estimate must be reliable.”
A large sample can be extremely valuable.
But sample size does not automatically repair:
- a badly chosen estimator,
- dependence that has been ignored,
- sampling bias,
- measurement error,
- distribution shift,
- infinite or poorly behaved moments,
- incorrect model assumptions.
More data helps when the statistical procedure has the right foundations.
It does not automatically make every method valid.
12. What About the Central Limit Theorem?
This experiment also connects naturally to another famous result: the Central Limit Theorem.
A familiar version of the CLT tells us that, under suitable conditions, appropriately normalised sums or sample means approach a Normal distribution.
This is one reason Normal approximations appear throughout statistics.
But again:
conditions matter.
The standard Cauchy distribution does not have finite variance—or even a finite mean.
The usual finite-variance Central Limit Theorem therefore does not apply to its sample mean.
In fact, the Cauchy distribution is a stable distribution.
Averages of independent Cauchy variables remain Cauchy.
So increasing sample size does not produce the familiar concentration and Normal approximation we may expect from finite-variance data.
13. Does This Mean the Cauchy Distribution Is Useless?
Not at all.
The Cauchy distribution is an important probability distribution.
It appears naturally in mathematics and physics, and it is a classic example for understanding why statistical assumptions matter.
The problem is not the distribution.
The problem is choosing an estimator whose target does not exist.
Trying to estimate the Cauchy population mean using the sample mean is fundamentally different from estimating the mean of a Normal distribution.
14. Use a Statistic That Actually Makes Sense
The Cauchy distribution has no finite mean.
But it does have a well-defined median.
For a standard Cauchy distribution:
median = 0
This gives us another experiment.
Instead of calculating the running mean, calculate the running median.
sample_sizes = [
    10,
    100,
    1000,
    10_000,
    100_000
]

for size in sample_sizes:

    rng = np.random.default_rng(42)

    x = rng.standard_cauchy(
        size=size
    )

    print(
        size,
        np.median(x)
    )
The sample median behaves very differently from the sample mean.
This reveals an important principle:
The problem is not always “bad data.” Sometimes the problem is using the wrong summary statistic for the distribution.
15. Mean vs Median
For light-tailed distributions without severe contamination, the sample mean can be an excellent estimator.
But the mean is sensitive to extreme values.
The median is much more robust.
Suppose we observe:
10, 11, 12, 12, 13
The mean and median are both close to 12.
Now change the final observation:
10, 11, 12, 12, 1000
The mean changes dramatically.
The median barely moves.
This does not mean:
“Median is always better than mean.”
It means:
Estimator choice should depend on the distribution, the data-generating process and the quantity we actually want to estimate.
16. What This Experiment Actually Shows
The experiment supports several conclusions.
1. More data can stabilise the sample mean when the required conditions are satisfied
The Normal experiment demonstrates the familiar behaviour.
2. Large sample size alone is not enough
For Cauchy data, the sample mean does not become increasingly concentrated around a finite population mean.
3. The theorem did not fail
The standard iid LLN for the sample mean is not contradicted because the Cauchy distribution does not satisfy the finite-mean condition needed for that result.
4. Heavy-tailed data require care
Extreme observations can continue to dominate familiar estimators.
5. Estimator choice matters
The median remains meaningful for the Cauchy distribution even though the population mean does not.
17. What This Experiment Does NOT Show
The experiment does not show:
“The Law of Large Numbers is unreliable.”
It is not.
It does not show:
“More data is useless.”
Usually, more high-quality data are extremely valuable.
It does not show:
“Never use the mean.”
The sample mean is one of the most useful estimators in statistics when its use is appropriate.
And it does not show:
“All heavy-tailed data behave like a Cauchy distribution.”
Heavy-tailed distributions differ substantially.
Some have finite means but infinite variance.
Some have both finite means and variances.
The Cauchy distribution is an intentionally extreme example.
18. A More Interesting Follow-Up Experiment
The natural next experiment is to move gradually from well-behaved distributions to increasingly heavy-tailed ones.
For example, compare:
- Normal,
- Student’s t with 10 degrees of freedom,
- Student’s t with 3 degrees of freedom,
- Student’s t with 1 degree of freedom.
The final case:
t(1)
is the Cauchy distribution.
Now compare:
- sample mean,
- sample median,
- trimmed mean.
Run each across increasing sample sizes and many random seeds.
Then measure:
- bias,
- variability,
- convergence behaviour,
- sensitivity to extreme observations.
That experiment would reveal something more nuanced than:
“Normal works, Cauchy doesn’t.”
It would show how estimator behaviour changes as the tails become heavier.
19. Why This Matters Beyond a Statistics Textbook
Real-world datasets can contain heavy tails.
Examples may appear in:
- financial returns,
- insurance losses,
- network traffic,
- file sizes,
- transaction values,
- wealth distributions,
- operational incidents.
Not all of these follow Cauchy distributions.
That is not the point.
The broader lesson is that assuming:
“We have millions of observations, therefore the average must be trustworthy”
can be dangerous.
Before trusting an estimator, we should ask:
What exactly are we estimating?
Does that population quantity exist?
What assumptions support the estimator?
How sensitive is it to the tails?
Are the observations actually independent?
Could sampling or measurement bias dominate the result?
These questions matter as much as sample size.
20. The Honest Write-Up
When I started this experiment, the tempting story was:
“Look—the Law of Large Numbers breaks!”
That makes a dramatic headline.
But it is not what happened.
The theorem did exactly what mathematics says it should do.
For the Normal distribution, its assumptions are satisfied and the sample mean behaves as expected.
For the Cauchy distribution, the finite population mean required by the standard result does not exist.
So the lesson is not that the Law of Large Numbers sometimes betrays us.
The lesson is:
A theorem is only as useful as our understanding of its assumptions.
That is less sensational.
It is also more important.
Conclusion
“Get more data” is often good advice.
But it is not a universal solution.
With well-behaved data and an appropriate estimator, increasing sample size can produce remarkable stability.
The Normal-distribution experiment shows exactly that.
The Cauchy experiment shows the boundary of that intuition.
Its sample mean does not settle around a finite population mean—not because probability theory has failed, but because the target we expected the average to recover does not exist.
So the practical lesson is not:
Never trust averages.
It is:
Before assuming that more data will stabilise an estimate, check what quantity you are estimating and whether the mathematical conditions supporting that expectation actually hold.
Sometimes the problem is insufficient data.
Sometimes the problem is the estimator.
And sometimes the population quantity we are trying to estimate is not defined in the first place.
References and Further Reading
[1] Kolmogorov, A. N. (1933). Foundations of the Theory of Probability.
A foundational treatment of modern probability theory and convergence concepts.
[2] Durrett, R. Probability: Theory and Examples. Cambridge University Press.
A rigorous modern reference covering laws of large numbers, convergence and related probability theory.
[3] NIST/SEMATECH. e-Handbook of Statistical Methods — Cauchy Distribution.
A practical reference for the properties of the Cauchy distribution.
https://www.itl.nist.gov/div898/handbook/eda/section3/eda3663.htm
[4] SciPy Documentation. scipy.stats.cauchy.
Reference implementation and distribution properties for the Cauchy distribution.
https://docs.scipy.org/doc/scipy/reference/generated/scipy.stats.cauchy.html
[5] NumPy Documentation. numpy.random.Generator.standard_cauchy.
Documentation for generating standard Cauchy random variables used in simulations.
https://numpy.org/doc/stable/reference/random/generated/numpy.random.Generator.standard_cauchy.html
Reproducibility and Interpretation Note
This article uses the standard Cauchy distribution as a deliberately extreme example because its ordinary finite mean and variance do not exist.
The experiment should not be interpreted as evidence that the Law of Large Numbers is false or unreliable.
Rather, it demonstrates that the familiar iid Law of Large Numbers for sample means requires conditions—including the existence of a finite expected value—that are not satisfied by the Cauchy distribution.
Individual simulated trajectories can also be visually misleading. For a stronger empirical demonstration, the experiment should be repeated across many independent random seeds and the distribution of the resulting estimators should be examined rather than relying on a single running-mean plot.
Related Reading
- Reproducing Double Descent: Why 300 Features Beat 39 on the Same 40 Data Points — another experiment where textbook statistical intuition needs a caveat
- Z-Score Thresholds vs. Isolation Forest: What Each Catches in Expense Fraud — a related look at when simple statistical assumptions miss real structure
- Honest Write-Up: When Does the CLT’s “n = 30” Rule Actually Hold? — a companion test of how slowly (not whether) the CLT converges for skewed-but-finite-variance populations
- More Data, Worse Model: Reproducing Sample-Wise Double Descent at n = d — another case where adding more data can transiently make a fixed, already-interpolating model worse, not better