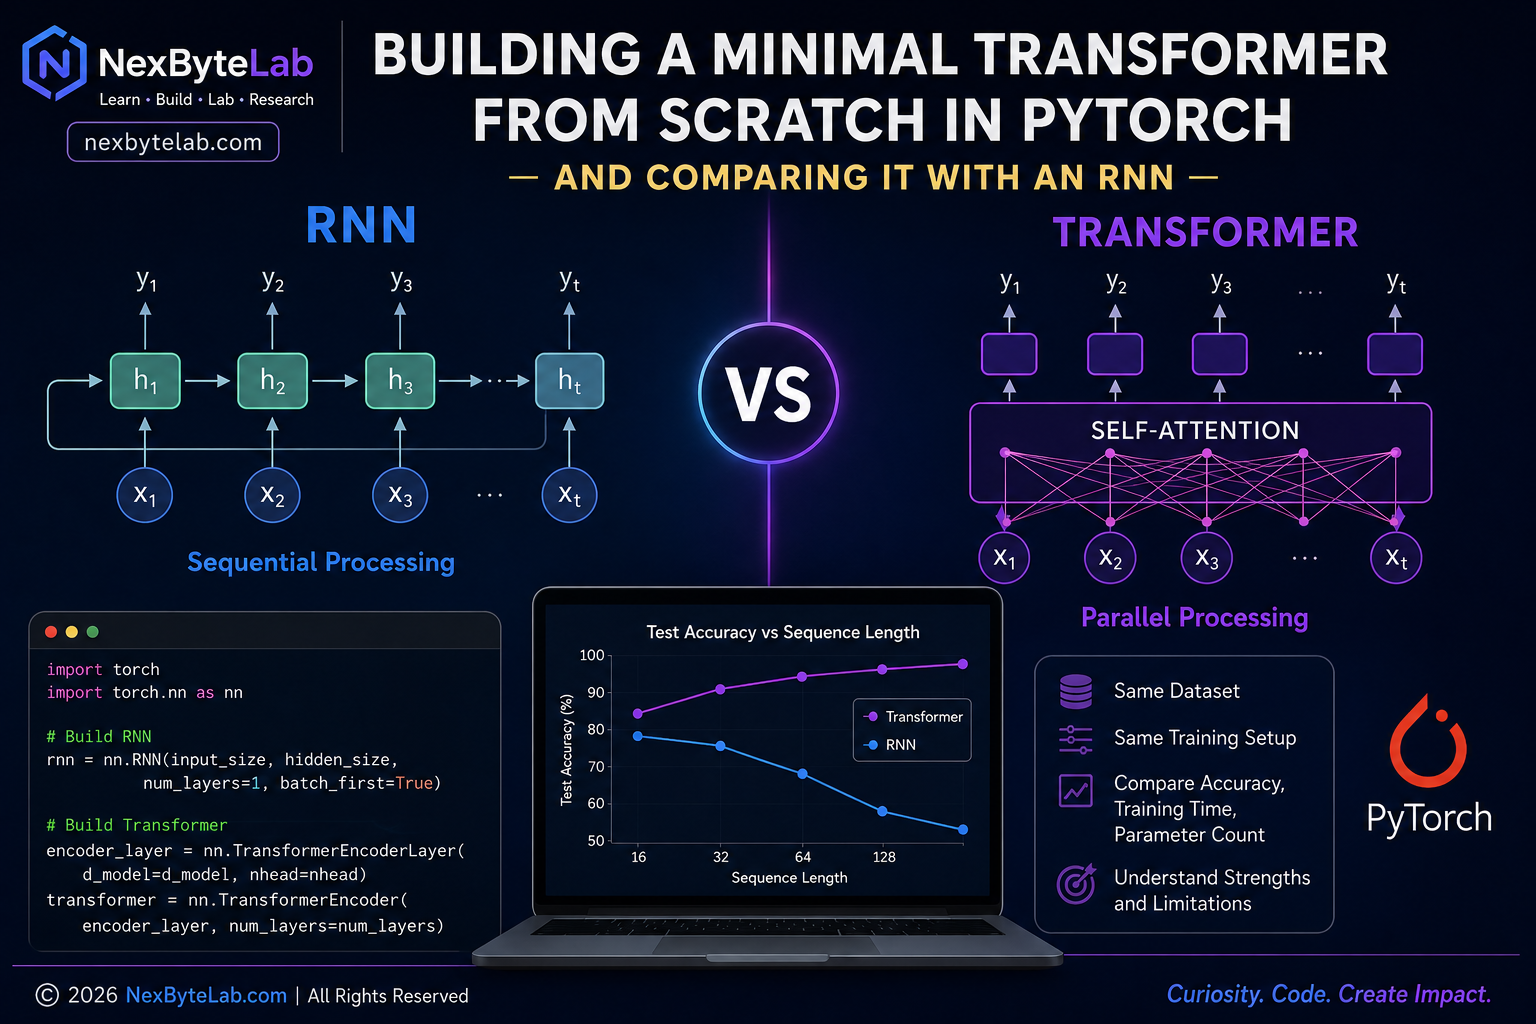
Building a Minimal Transformer From Scratch in PyTorch — and Comparing It With an RNN
Building a Minimal Transformer From Scratch in PyTorch — and Comparing It With an RNN
In the previous article, we explored the idea behind Transformers: instead of processing a sequence strictly one element at a time, a Transformer uses self-attention to model relationships between positions in that sequence.
But understanding an architecture on paper and observing its behaviour are two different things.
So this time, we are going to turn the idea into a small reproducible experiment.
If we give a simple RNN and a small Transformer the same sequence-learning problem, what differences should we measure — and how can we compare them fairly?
We will build both models in PyTorch, train them using the same synthetic dataset and training procedure, and define exactly what should be measured.
There is one important distinction upfront:
This article provides the complete experimental setup and code. It does not report benchmark results that have not been measured.
That matters.
The objective is not to manufacture a result that says:
“Transformers are better than RNNs.”
One small experiment could never justify such a broad conclusion.
Instead, the objective is to understand how to design a controlled comparison that makes the architectural differences between recurrence and self-attention observable.
1. The Research Question
Our experiment begins with a simple question:
How does a Transformer compare with a basic recurrent neural network when learning a dependency between distant positions in a sequence?
This question matters because RNNs and Transformers process sequences in fundamentally different ways.
A traditional RNN maintains a hidden state that evolves as it moves through the sequence. In simplified form, PyTorch expresses the recurrence as:
hₜ = tanh(xₜWᵀᵢₕ + bᵢₕ + hₜ₋₁Wᵀₕₕ + bₕₕ)
The representation at time t therefore depends partly on the hidden state produced at time t − 1 [1].
A Transformer takes a different approach.
Vaswani and colleagues introduced an architecture that removed recurrence from its core and relied instead on attention mechanisms. This allows relationships between positions to be modelled more directly and allows much of the sequence computation to be parallelised during training [2].
Our experiment is designed to make that architectural difference easier to observe.
2. Our Hypothesis
Before running an experiment, we should state what we expect.
Hypothesis
For a task requiring information from distant positions in a sequence:
A Transformer should be able to learn the dependency effectively because self-attention allows information at distant positions to interact within an attention layer. A simple RNN may find the same dependency increasingly difficult as sequence length grows because information is propagated recurrently through successive hidden states.
Notice the wording.
We are not saying:
“The Transformer will always beat the RNN.”
That would not be scientifically defensible.
Performance depends on the task, dataset, architecture, sequence length, parameter count, optimisation procedure, random initialisation, software implementation, hardware and many other factors.
Our hypothesis applies only to this experimental setup.
3. Designing a Controlled Experiment
Real-world language datasets introduce many variables:
- vocabulary size,
- tokenisation,
- ambiguous language,
- class imbalance,
- noisy labels,
- pretrained embeddings,
- dataset-specific biases,
- and semantic complexity.
Those variables matter in real applications, but they make it harder to isolate why two architectures behave differently.
So we will deliberately begin with a synthetic dataset.
Synthetic data gives us something valuable:
we know exactly what relationship the model must learn.
4. The Task: Can the Model Detect a Distant Relationship?
Consider this sequence:
3 8 1 4 7 2 9 6 5 3
The first token is 3.
The final token is also 3.
The label is therefore:
1
Now consider:
3 8 1 4 7 2 9 6 5 6
The first and final tokens are different.
The label becomes:
0
Our classification rule is:
Label = 1 if the first token equals the final token; otherwise label = 0.
Why use such an artificial task?
Because the relationship is completely known.
The model cannot reliably solve the task by examining only the final token. It needs information about both ends of the sequence.
More importantly, we can increase the distance between those relevant positions simply by increasing sequence length.
That gives us a small laboratory for studying long-range sequence dependency.
5. Experimental Controls
For the first experiment, we keep the major training conditions the same wherever practical.
| Variable | Setting |
|---|---|
| Task | Binary sequence classification |
| Vocabulary | Digits 0–9 |
| Training samples | 6,000 |
| Test samples | 2,000 |
| Sequence length | 64 |
| Embedding dimension | 64 |
| Optimizer | Adam |
| Learning rate | 0.002 |
| Batch size | 128 |
| Loss function | Cross-entropy |
| Random seed | 42 |
There is an important caveat.
Using the same embedding dimension does not mean the models contain the same number of trainable parameters.
A Transformer and an RNN contain different internal components.
Therefore, we will report parameter counts rather than calling the experiment “perfectly fair.”
That distinction matters in serious model comparison.
6. Make the Experiment Reproducible
Machine-learning experiments contain randomness.
Weights are randomly initialised. Training samples may be shuffled. Some hardware operations can also introduce nondeterministic behaviour.
We therefore begin by setting random seeds.
import random
import time

import numpy as np
import torch
import torch.nn as nn
from torch.utils.data import DataLoader, TensorDataset

SEED = 42

random.seed(SEED)
np.random.seed(SEED)
torch.manual_seed(SEED)

if torch.cuda.is_available():
    torch.cuda.manual_seed_all(SEED)

device = torch.device(
    "cuda" if torch.cuda.is_available() else "cpu"
)

print("Device:", device)
Setting a seed does not guarantee bit-for-bit identical results across every PyTorch version, device and hardware configuration.
But it removes an important source of uncontrolled variation.
7. Generate the Dataset
We now create the synthetic sequences.
VOCAB_SIZE = 10
SEQ_LEN = 64

TRAIN_SIZE = 6000
TEST_SIZE = 2000


def create_dataset(size, seed):

    generator = torch.Generator()
    generator.manual_seed(seed)

    X = torch.randint(
        0,
        VOCAB_SIZE,
        (size, SEQ_LEN),
        generator=generator
    )

    y = torch.randint(
        0,
        2,
        (size,),
        generator=generator
    )

    same = y == 1
    different = y == 0

    # Positive examples:
    # first token == last token
    X[same, -1] = X[same, 0]

    # Negative examples:
    # guarantee last token != first token
    offsets = torch.randint(
        1,
        VOCAB_SIZE,
        (different.sum(),),
        generator=generator
    )

    X[different, -1] = (
        X[different, 0] + offsets
    ) % VOCAB_SIZE

    return X, y


X_train, y_train = create_dataset(
    TRAIN_SIZE,
    seed=1
)

X_test, y_test = create_dataset(
    TEST_SIZE,
    seed=2
)
Positive and negative examples are generated with approximately equal probability.
That matters because otherwise a model might achieve apparently impressive accuracy simply by repeatedly predicting the majority class.
8. Build the RNN Baseline
A baseline is essential in machine learning.
Without one, saying that a model achieves 90% accuracy tells us surprisingly little.
Perhaps a much simpler model achieves 95%.
Our baseline is a basic Elman RNN.
class RNNClassifier(nn.Module):

    def __init__(
        self,
        vocab_size=10,
        embedding_dim=64,
        hidden_dim=64
    ):

        super().__init__()

        self.embedding = nn.Embedding(
            vocab_size,
            embedding_dim
        )

        self.rnn = nn.RNN(
            input_size=embedding_dim,
            hidden_size=hidden_dim,
            batch_first=True
        )

        self.classifier = nn.Linear(
            hidden_dim,
            2
        )

    def forward(self, x):

        x = self.embedding(x)

        output, hidden = self.rnn(x)

        final_hidden = hidden[-1]

        return self.classifier(final_hidden)
Conceptually:
x₁ → h₁ → h₂ → h₃ → ... → h₆₄ → prediction
Information from the beginning of the sequence has to influence the hidden state repeatedly until the final state used for classification.
PyTorch’s nn.RNN implements this recurrent hidden-state structure directly [1].
9. Build the Minimal Transformer
Now we build the Transformer classifier.
For educational clarity, we will use PyTorch’s TransformerEncoderLayer.
class TransformerClassifier(nn.Module):

    def __init__(
        self,
        vocab_size=10,
        seq_len=64,
        d_model=64,
        nhead=4,
        dim_feedforward=128,
        num_layers=2
    ):

        super().__init__()

        self.embedding = nn.Embedding(
            vocab_size,
            d_model
        )

        self.position = nn.Parameter(
            torch.randn(
                1,
                seq_len,
                d_model
            ) * 0.02
        )

        encoder_layer = nn.TransformerEncoderLayer(
            d_model=d_model,
            nhead=nhead,
            dim_feedforward=dim_feedforward,
            dropout=0.0,
            batch_first=True
        )

        self.encoder = nn.TransformerEncoder(
            encoder_layer,
            num_layers=num_layers
        )

        self.classifier = nn.Linear(
            d_model,
            2
        )

    def forward(self, x):

        x = self.embedding(x)

        x = x + self.position[:, :x.size(1)]

        x = self.encoder(x)

        final_token = x[:, -1]

        return self.classifier(final_token)
There is an important architectural difference here.
After self-attention, the representation at the final position can incorporate information from the first position without that information having to be propagated through 63 recurrent hidden-state transitions.
That does not guarantee that the Transformer will learn the task better.
It means the architecture provides a different computational path for modelling the dependency.
10. Attention in One Equation
The central scaled dot-product attention operation introduced by Vaswani et al. is:
Attention(Q, K, V) = softmax(QKᵀ / √dₖ)V
[2]
At a high level:
- construct queries representing what positions are looking for,
- compare them with keys representing other positions,
- calculate attention scores,
- normalise those scores,
- use them to combine the corresponding values.
For our synthetic task, the network has the opportunity to learn that information at the beginning of the sequence is useful when constructing the representation used for classification.
11. Use the Same Training Procedure
Both models should go through the same training procedure.
def train_model(
    model,
    train_loader,
    test_loader,
    epochs=8,
    learning_rate=0.002
):

    model = model.to(device)

    optimizer = torch.optim.Adam(
        model.parameters(),
        lr=learning_rate
    )

    criterion = nn.CrossEntropyLoss()

    history = []

    start_time = time.perf_counter()

    for epoch in range(epochs):

        model.train()

        total_loss = 0
        correct = 0
        total = 0

        for X_batch, y_batch in train_loader:

            X_batch = X_batch.to(device)
            y_batch = y_batch.to(device)

            optimizer.zero_grad()

            predictions = model(X_batch)

            loss = criterion(
                predictions,
                y_batch
            )

            loss.backward()
            optimizer.step()

            total_loss += (
                loss.item() * y_batch.size(0)
            )

            predicted_labels = (
                predictions.argmax(dim=1)
            )

            correct += (
                predicted_labels == y_batch
            ).sum().item()

            total += y_batch.size(0)

        train_accuracy = correct / total
        train_loss = total_loss / total

        model.eval()

        test_correct = 0
        test_total = 0

        with torch.no_grad():

            for X_batch, y_batch in test_loader:

                X_batch = X_batch.to(device)
                y_batch = y_batch.to(device)

                predictions = model(X_batch)

                predicted_labels = (
                    predictions.argmax(dim=1)
                )

                test_correct += (
                    predicted_labels == y_batch
                ).sum().item()

                test_total += y_batch.size(0)

        test_accuracy = (
            test_correct / test_total
        )

        history.append({
            "epoch": epoch + 1,
            "loss": train_loss,
            "train_accuracy": train_accuracy,
            "test_accuracy": test_accuracy
        })

        print(
            f"Epoch {epoch + 1:02d} | "
            f"Loss: {train_loss:.4f} | "
            f"Train Acc: {train_accuracy:.4f} | "
            f"Test Acc: {test_accuracy:.4f}"
        )

    elapsed = (
        time.perf_counter() - start_time
    )

    return model, history, elapsed
Using the same training loop reduces one source of unnecessary variation between the two models.
12. Prepare the DataLoaders
BATCH_SIZE = 128

train_dataset = TensorDataset(
    X_train,
    y_train
)

test_dataset = TensorDataset(
    X_test,
    y_test
)

train_loader = DataLoader(
    train_dataset,
    batch_size=BATCH_SIZE,
    shuffle=True
)

test_loader = DataLoader(
    test_dataset,
    batch_size=BATCH_SIZE
)
Both models now see the same training and test examples.
13. Count the Parameters
Before comparing performance, we should know the size of each model.
def count_parameters(model):

    return sum(
        p.numel()
        for p in model.parameters()
        if p.requires_grad
    )


rnn_model = RNNClassifier()

transformer_model = TransformerClassifier()

print(
    "RNN parameters:",
    count_parameters(rnn_model)
)

print(
    "Transformer parameters:",
    count_parameters(transformer_model)
)
Why report this?
Because model capacity itself can influence performance.
If one model contains substantially more trainable parameters, that becomes an important qualification when interpreting the comparison.
14. Run the RNN
torch.manual_seed(SEED)

rnn_model = RNNClassifier()

rnn_model, rnn_history, rnn_time = train_model(
    rnn_model,
    train_loader,
    test_loader
)

print(
    "RNN training time:",
    round(rnn_time, 2),
    "seconds"
)
Record the output.
Do not decide yet whether the RNN is “good” or “bad.”
We still need the comparison.
15. Run the Transformer
torch.manual_seed(SEED)

transformer_model = TransformerClassifier()

transformer_model, transformer_history, transformer_time = train_model(
    transformer_model,
    train_loader,
    test_loader
)

print(
    "Transformer training time:",
    round(transformer_time, 2),
    "seconds"
)
We now have two observations produced using the same dataset and broadly comparable training conditions.
16. Record the Results — Don’t Invent Them
Once the experiment has been executed, record the actual outputs.
| Metric | RNN | Transformer |
|---|---|---|
| Trainable parameters | Measured result | Measured result |
| Final training loss | Measured result | Measured result |
| Final training accuracy | Measured result | Measured result |
| Final test accuracy | Measured result | Measured result |
| Training time | Measured result | Measured result |
The placeholders here are intentional.
Benchmark numbers should be measured, not imagined.
Training time in particular depends heavily on CPU/GPU hardware, PyTorch version, device implementation, batch size and other environmental factors.
When publishing measured results, record the environment alongside them.
17. What Should We Look For?
Accuracy alone is not enough.
There are at least four useful observations.
1. Learning behaviour
How quickly does training loss fall?
Does one model learn the dependency earlier than the other?
The full learning curve is often more informative than a single final accuracy number.
2. Generalisation
Compare training and test accuracy.
A model achieving:
Training accuracy: 99%Test accuracy: 55%
has behaved very differently from one achieving:
Training accuracy: 95%Test accuracy: 94%
The latter is generalising much better to unseen examples.
3. Computational time
Measure training time, but interpret it carefully.
The original Transformer paper highlighted the architecture’s parallelisability [2].
That does not mean a tiny Transformer must always run faster than a tiny RNN on every CPU or GPU.
Hardware, sequence length, batch size and implementation all matter.
4. Parameter count
A model that wins while using substantially more parameters leads to a different conclusion from a similarly sized model that wins.
Always report model size.
18. The More Interesting Experiment: Increase Sequence Length
A single sequence length tells us only so much.
The more interesting experiment is to vary the distance between the two relevant positions.
Repeat the experiment using:
SEQ_LEN = 16
then:
SEQ_LEN = 32
then:
SEQ_LEN = 64
and:
SEQ_LEN = 128
Record the results.
| Sequence length | RNN test accuracy | Transformer test accuracy |
|---|---|---|
| 16 | Measured result | Measured result |
| 32 | Measured result | Measured result |
| 64 | Measured result | Measured result |
| 128 | Measured result | Measured result |
Now we have deliberately manipulated an independent variable:
sequence length
and observed a dependent variable:
model performance.
The question becomes much more interesting:
What happens to each architecture as the distance between relevant positions increases?
That is a stronger experiment than simply training two models once.
19. Why Might the Architectures Behave Differently?
Consider the RNN.
For information from the first position to affect the final hidden state, it participates in a chain of recurrent computations:
h₁ → h₂ → h₃ → h₄ → ... → h₆₄
The hidden state acts as continually updated memory.
The Transformer creates a different computational structure.
Within a self-attention layer, representations at different positions can interact without requiring information to pass sequentially through every intermediate position.
Vaswani et al. discussed these shorter paths between long-range dependencies as one motivation for self-attention [2].
That does not guarantee superior accuracy.
It changes the route through which information can flow.
And that is the architectural distinction our experiment is designed to investigate.
20. Transformers Have Their Own Cost
At this point it would be tempting to conclude:
“Transformers handle long dependencies, therefore Transformers are always superior.”
That conclusion would be wrong.
Standard self-attention has its own computational cost.
For a sequence containing n tokens, the attention score matrix contains relationships between pairs of positions. Standard attention therefore has approximately quadratic computation and memory requirements with respect to sequence length for the attention matrix.
Conceptually:
sequence length = n
attention relationships ≈ n × n
Increasing context length can therefore become expensive.
This limitation has motivated extensive research into efficient attention, sparse attention and alternative architectures for long sequences.
Every architecture makes trade-offs.
21. What Would This Experiment Actually Prove?
Even after running it, the answer is:
not that Transformers are universally better than RNNs.
The results would apply only to:
- this synthetic task,
- these particular architectures,
- these hyperparameters,
- these training conditions,
- these sequence lengths,
- these random seeds,
- and the software/hardware environment used.
There is another important limitation.
Our baseline is a basic Elman RNN.
LSTMs and GRUs were designed specifically to improve recurrent networks’ ability to preserve useful information over longer sequences.
So this experiment should not be interpreted as:
“Attention versus the best possible recurrent model.”
It is:
a minimal Transformer versus a basic RNN on a controlled synthetic dependency task.
That is a much narrower—and much more defensible—claim.
22. A Better Version: Multiple Random Seeds
One run can be misleading.
Weight initialisation and data ordering can affect training outcomes.
A stronger experiment would repeat every model/sequence-length combination across several random seeds.
For example:
SEEDS = [1, 2, 3, 4, 5]
Then report:
mean test accuracy ± standard deviation
instead of reporting only one number.
The result table could become:
| Sequence length | RNN accuracy | Transformer accuracy |
|---|---|---|
| 16 | mean ± SD | mean ± SD |
| 32 | mean ± SD | mean ± SD |
| 64 | mean ± SD | mean ± SD |
| 128 | mean ± SD | mean ± SD |
This would tell us whether an apparent advantage is reasonably consistent or simply the result of one favourable random run.
23. Turning a Tutorial Into an Experiment
This example illustrates an important difference between learning machine learning and experimenting with machine learning.
A tutorial asks:
How do I build a Transformer?
An experiment asks:
Under what conditions does the Transformer behave differently from the baseline, and what evidence supports that conclusion?
That change in question forces us to think about:
- hypotheses,
- baselines,
- controls,
- metrics,
- parameter counts,
- random seeds,
- reproducibility,
- confounding variables,
- limitations,
- and evidence.
Those habits matter far beyond Transformers.
They are fundamental to good experimental machine learning.
24. What We Can Learn Before Seeing the Results
Even without inventing benchmark numbers, the architecture itself tells us something important.
The RNN and Transformer create fundamentally different computational paths through a sequence.
An RNN repeatedly updates a hidden state:
previous state + current input → new state
A Transformer uses self-attention to allow representations at different positions to interact.
The experiment is designed to measure the consequences of those architectural choices.
The result may favour the Transformer.
It may favour the RNN under some conditions.
It may reveal that both solve short sequences easily and diverge only as sequence length increases.
Any of those outcomes would be informative if they were actually measured.
That is the point.
The purpose of an experiment is not to confirm the story we wanted to tell. It is to find out what happens.
25. The Bigger Lesson
Perhaps the most important lesson here has little to do with Transformers.
When someone claims:
“Model A is better than Model B,”
we should immediately ask:
Better at what?
Then:
On which dataset?
Using which metric?
With how many parameters?
Using what hyperparameters?
Across how many runs?
On what hardware?
Was everything else held reasonably constant?
And finally:
Does the evidence support the size of the claim being made?
Those questions separate an experiment from a demonstration—and a benchmark from a marketing claim.
The goal of machine-learning experimentation is not merely to obtain a number.
It is to understand why we obtained it, how reliable it is, and under what conditions it remains true.
Next Experiment
This experiment naturally raises another question.
If a basic RNN struggles as dependencies become longer, what happens when we compare the Transformer with recurrent architectures specifically designed to improve long-term memory?
A stronger follow-up would therefore be:
RNN vs LSTM vs GRU vs Transformer: What Happens as Sequence Length Grows?
Instead of testing only one sequence length, we could systematically vary:
16 → 32 → 64 → 128 → 256
Run every configuration across multiple seeds.
Then report:
- mean test accuracy,
- standard deviation,
- parameter count,
- training time,
- learning curves,
- and behaviour as sequence length increases.
At that point, we would have moved beyond a coding demonstration.
We would have a small reproducible machine-learning study.
References
[1] PyTorch Documentation. torch.nn.RNN.
PyTorch’s implementation and mathematical definition of a multi-layer Elman RNN.
https://docs.pytorch.org/docs/stable/generated/torch.nn.RNN.html
[2] Vaswani, A., Shazeer, N., Parmar, N., et al. (2017). Attention Is All You Need. Advances in Neural Information Processing Systems 30.
https://arxiv.org/abs/1706.03762
[3] PyTorch Documentation. TransformerEncoderLayer.
Reference implementation containing self-attention and feed-forward components based on the original Transformer architecture.
https://docs.pytorch.org/docs/stable/generated/torch.nn.TransformerEncoderLayer.html
[4] PyTorch Documentation. TransformerEncoder.
PyTorch reference implementation of a stack of Transformer encoder layers.
https://docs.pytorch.org/docs/stable/generated/torch.nn.TransformerEncoder.html
Reproducibility Note
The code in this article deliberately uses a synthetic dataset so that the experiment can be reproduced without downloading proprietary data or relying on external APIs.
The article does not report unmeasured benchmark results.
Any future benchmark table added to this article should contain results produced by actually executing the experiment and should record, at minimum, the random seeds, PyTorch version, hardware/device and relevant experimental configuration used.
Related Reading
- Transformers Explained: The Architecture that changed Modern AI — the conceptual background behind the architecture built from scratch here
- Papers Explained: Attention Is All You Need — the original paper that introduced the architecture this post implements