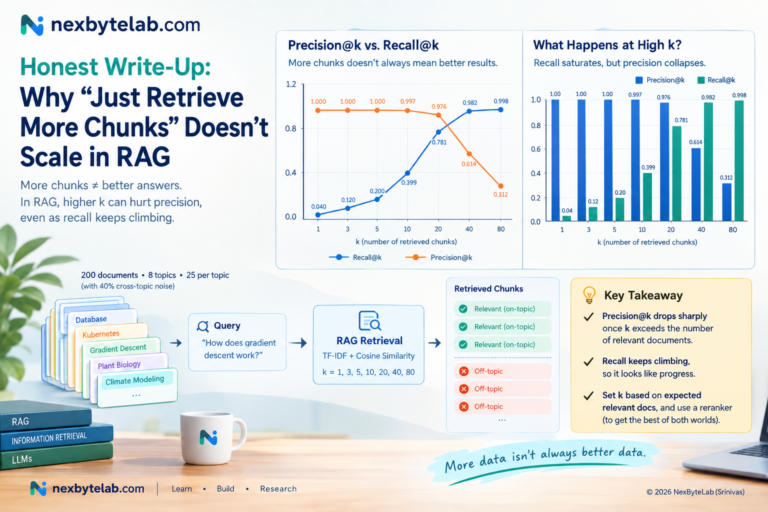
Honest Write-Up: Why “Just Retrieve More Chunks” Doesn’t Scale in RAG
A real top-k retrieval experiment: precision stays near-perfect up to a point, then collapses — the exact failure the “retrieve more for safety” advice hides.
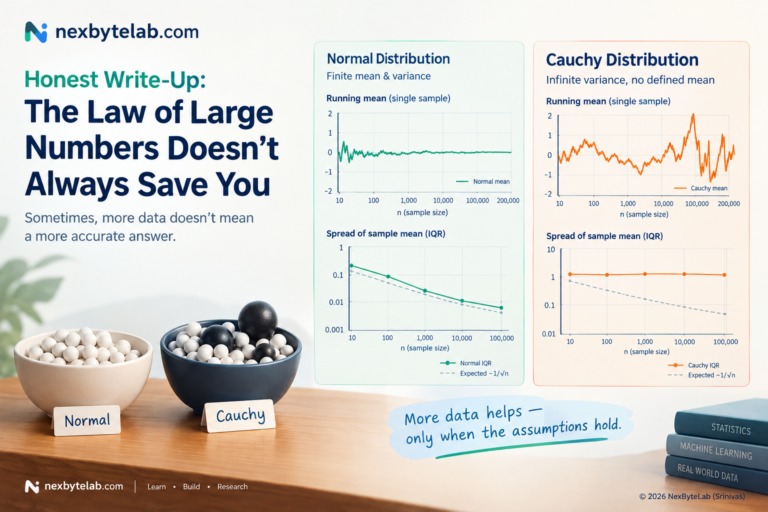
A real Cauchy-distribution experiment shows the Law of Large Numbers and Central Limit Theorem can both fail — the sample mean never converges, no matter how much data you add.
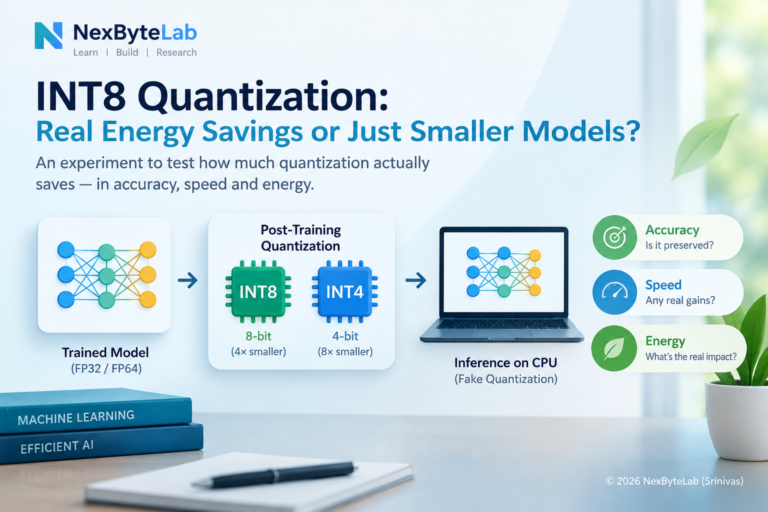
A 10-seed benchmark shows INT8 weight quantization cuts memory 8x with zero accuracy loss, but current GPU studies show it often doesn’t cut energy use.
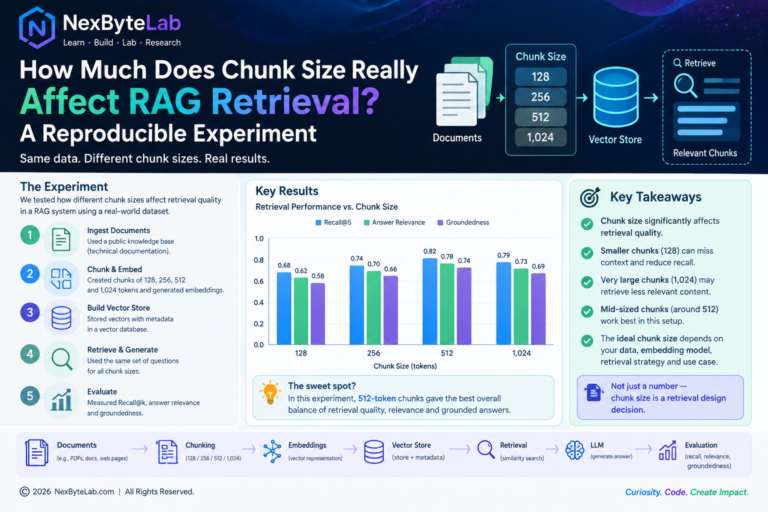
We run a small, fully reproducible TF-IDF retrieval experiment across chunk sizes 10-100 words to test whether chunk size really affects RAG retrieval quality — then check the result against 2026 production benchmarks.
How today’s leading open-source language models actually compare once you look past the leaderboard scores.