Building Your First RAG Agent: From Documents to Grounded AI
Building your first RAG agent starts with a simple failure: watching an LLM answer confidently and wrong.
Large Language Models can write, summarise, explain and reason remarkably well.
But ask one:
“What does our company’s latest leave policy say about carrying unused leave into next year?”
and an interesting problem appears.
Unless that policy was included in the model’s context—or somehow represented in its training—the model does not automatically have access to the document sitting inside your organisation.
It may say:
“I don’t know.”
Worse, it may produce an answer that sounds perfectly reasonable but is unsupported by your actual policy.
This is one of the problems Retrieval-Augmented Generation, or RAG, is designed to address.
Instead of expecting the language model to contain every fact inside its parameters, RAG gives it a way to retrieve relevant information from an external knowledge source at the time a question is asked.
The basic idea is remarkably intuitive:
Search first. Read the evidence. Then answer.
In this research brief, we will go one step further.
We will understand how a basic RAG system works, design one from first principles, and then examine what must change before we can reasonably call it a RAG agent.
1. What Problem Is RAG Actually Solving?
Imagine you have 5,000 pages of internal documentation:
- HR policies,
- product manuals,
- research papers,
- operating procedures,
- technical documentation,
- project reports,
- FAQs,
- and meeting notes.
A user asks:
“How many days of parental leave are employees entitled to?”
One approach would be to paste thousands of pages into the language model.
That is usually undesirable.
It consumes context, increases computational cost, and can make relevant evidence harder for a model to use effectively.
Research by Liu et al. found that language-model performance can degrade depending on where relevant information occurs within a long context; simply providing more context does not guarantee that the model will use it effectively [5].
RAG takes another approach.
First identify the small pieces of information most relevant to the question.
Then give those pieces to the language model.
Conceptually:
5,000 pages
↓
Retrieve perhaps 3–5 relevant passages
↓
Give those passages + question to the LLM
↓
Generate an answer grounded in the retrieved evidence
This is the central intuition behind RAG.
2. Where Did RAG Come From?
The term Retrieval-Augmented Generation became widely established through the 2020 paper:
“Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks”
by Patrick Lewis and colleagues [1].
The researchers described language models as containing parametric memory—knowledge encoded in the model’s learned parameters—and combined this with non-parametric memory, represented by an external collection of retrieved documents.
Their experiments showed that retrieval-augmented models could produce more specific and factual language than the parametric-only baseline used in their study and achieved strong results on knowledge-intensive tasks [1].
That gives us a useful mental model:
Traditional LLM
Question → Model → Answer
RAG
Question → Retrieval → Relevant evidence → Model → Answer
The language model has not necessarily “learned” your documents.
Instead, the documents are supplied as evidence when they are needed.
3. A Library Is a Better Analogy Than a Brain
Imagine asking a professor a difficult question.
There are two possible approaches.
Approach A
The professor answers entirely from memory.
Approach B
The professor searches a library, finds three relevant papers, reads the important sections, and then answers your question using those sources.
RAG resembles the second approach.
The language model remains responsible for interpreting and generating the answer.
But an external retrieval system supplies potentially useful evidence.
This distinction is fundamental:
RAG does not primarily put new knowledge inside the model. It gives the model access to external knowledge during inference.
That is why a RAG knowledge base can often be updated without retraining the underlying LLM.
4. The Architecture of a Minimal RAG System
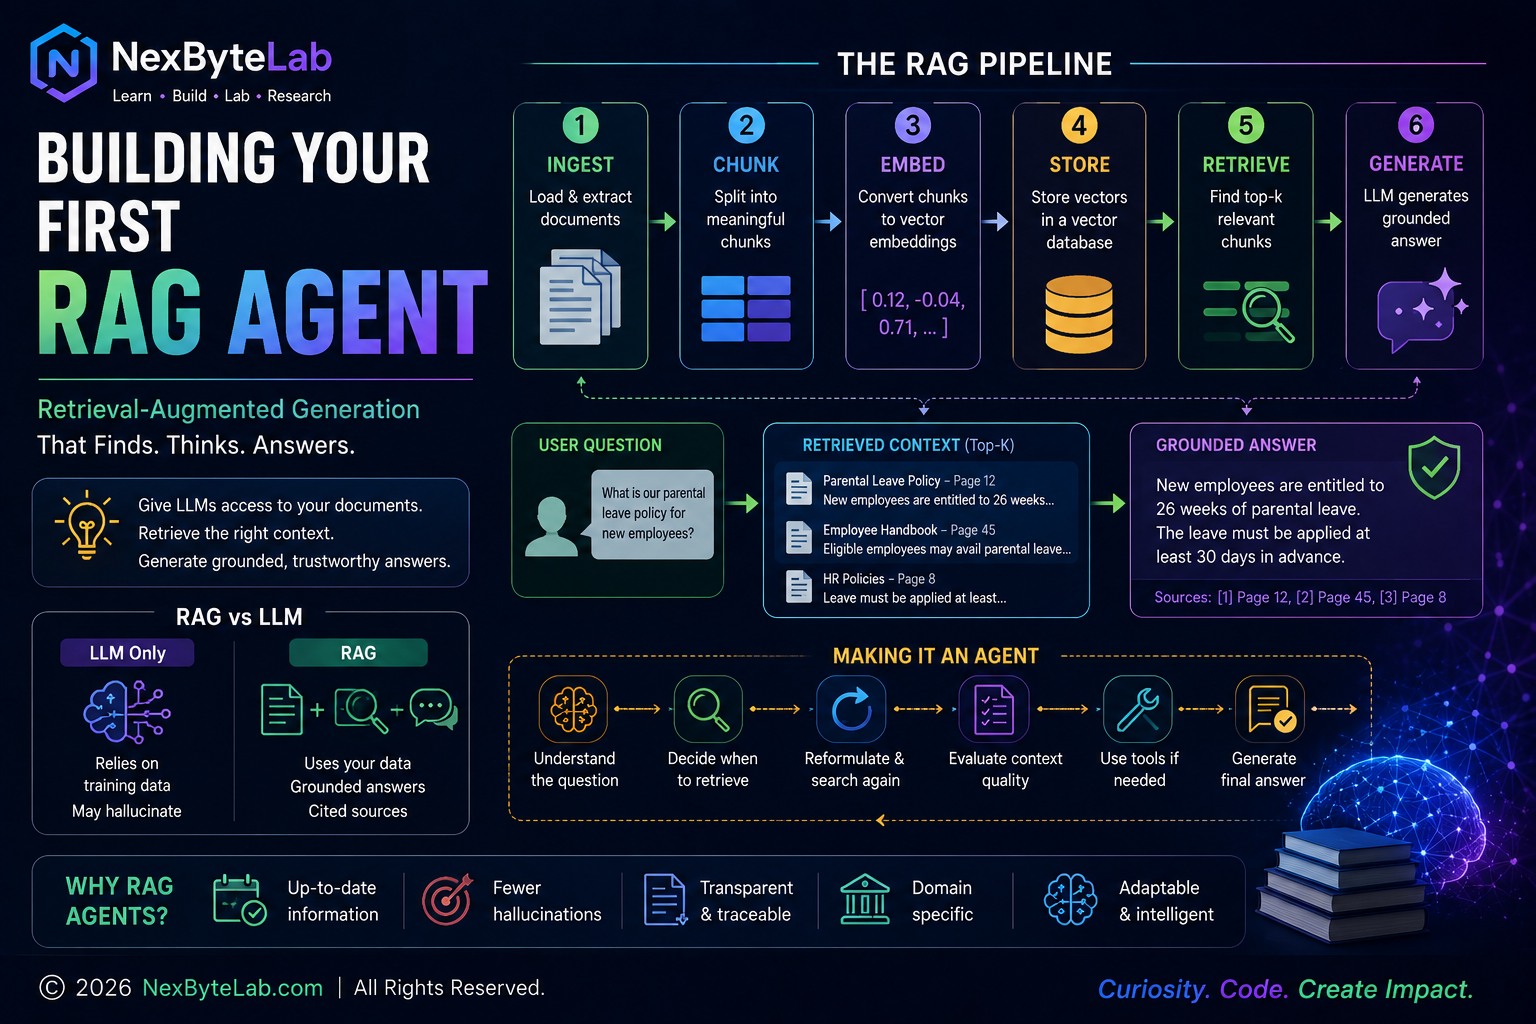
A basic RAG system can be understood as two pipelines.
Pipeline A — Indexing
This happens before users ask questions.
Documents
↓
Extract text
↓
Split into chunks
↓
Create embeddings
↓
Store chunks + embeddings + metadata
Pipeline B — Question Answering
This happens when the user asks something.
User question
↓
Create query representation
↓
Retrieve relevant chunks
↓
Construct prompt/context
↓
LLM generates answer
↓
Return answer + supporting sources
This separation between indexing and retrieval/generation is useful because the expensive document preparation does not need to be repeated for every question.
Let’s examine each component.
5. Step One: Collect the Knowledge Base
Suppose we want to create an assistant that answers questions about an organisation’s policies.
Our knowledge base might contain:
leave_policy.pdf
travel_policy.pdf
remote_work_policy.pdf
insurance_policy.pdf
code_of_conduct.pdf
The first challenge is converting these documents into reliable machine-readable text.
That sounds trivial until real documents arrive.
PDFs may contain:
- tables,
- headers,
- footers,
- scanned pages,
- multi-column layouts,
- charts,
- repeated navigation,
- and broken text extraction.
This creates our first important research lesson:
A RAG system can only retrieve information that survived the ingestion process.
If the source was extracted incorrectly, even an excellent retriever and LLM cannot reliably recover the missing evidence.
6. Step Two: Why Do We Need Chunking?
Suppose our leave policy contains 80 pages.
We could store the entire document as one searchable object.
But then a question about parental leave might retrieve all 80 pages.
That defeats much of the purpose of retrieval.
Instead, documents are usually divided into smaller units called chunks.
For example:
Document

Employee Leave Policy
        ↓

Chunk 1
Annual Leave Eligibility

Chunk 2
Carry Forward Rules

Chunk 3
Parental Leave

Chunk 4
Sick Leave

Chunk 5
Leave Encashment
Now a question about parental leave can retrieve the relevant section rather than the entire policy.
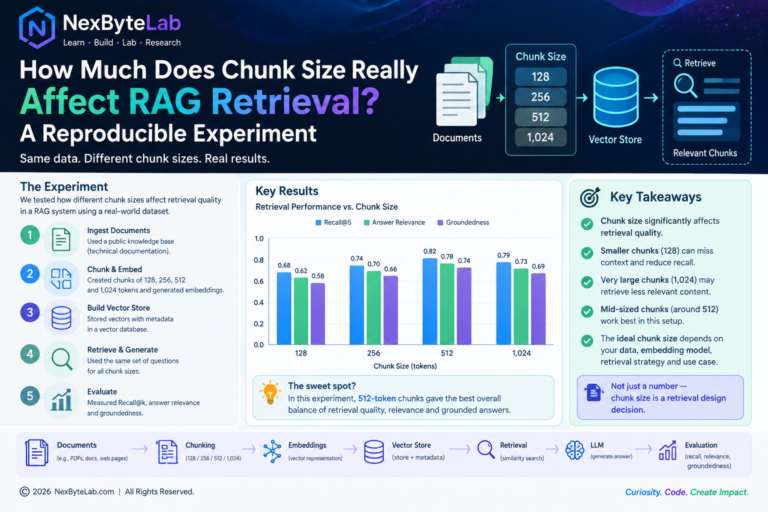
7. How Large Should a Chunk Be?
You will often encounter advice such as:
“Use 500-token chunks.”
That can be a reasonable starting point.
It is not a universal scientific rule.
Chunk size depends on:
- document structure,
- information density,
- retrieval model,
- question type,
- context window,
- overlap strategy,
- and evaluation results.
Imagine a policy statement:
“Employees may carry forward unused annual leave subject to the limits described in Section 8.”
If the chunk ends immediately after “subject to the limits,” while Section 8 lands in another unrelated chunk, the evidence becomes fragmented.
This is why chunking is not merely a preprocessing detail.
It is a retrieval design decision.
A better research question is therefore not:
“What is the best chunk size?”
but:
“Which chunking strategy produces the best retrieval performance for our documents and questions?”
That is something we can experimentally measure.
8. Step Three: Convert Text Into Embeddings
Computers need a numerical representation of text before they can efficiently compare semantic similarity.
An embedding model converts text into a vector.
Conceptually:
"Employees receive 20 days annual leave"

        ↓ embedding model

[0.18, -0.42, 0.71, 0.09, ...]
The vector may contain hundreds or thousands of dimensions depending on the embedding model.
You should not interpret individual dimensions as simple human-readable concepts.
Instead, the vector represents information in a learned numerical space.
Texts with similar semantic content can often be located near one another in that space.
9. Semantic Search vs Keyword Search
Consider a document containing:
“Employees may perform their duties away from company premises for up to three days per week.”
A user asks:
“How many days can I work from home?”
A literal keyword system may look for:
work from home
But those exact words never appear.
An embedding-based retriever can potentially recognise that:
work from home
and
perform duties away from company premises
are semantically related.
This is one reason dense retrieval became important in modern information retrieval.
However, semantic retrieval is not automatically superior for every query.
Exact identifiers such as:
INC-2026-00451
SAP-X92
Policy HR-17
may be better served by lexical or keyword matching.
For this reason, practical RAG systems may use hybrid retrieval, combining semantic and lexical signals.
The broader RAG literature has evolved well beyond a single vector-search pipeline; surveys distinguish naive, advanced and modular RAG architectures [2].
10. Step Four: Store the Knowledge
After creating embeddings, we need somewhere to store them.
Conceptually, each record might contain:
Vector:
[0.18, -0.42, 0.71, ...]

Text:
"Employees are entitled to..."

Source:
leave_policy.pdf

Page:
17

Section:
Parental Leave
Notice that we store more than the vector.
The metadata matters.
Useful metadata may include:
- document name,
- page number,
- section heading,
- publication date,
- document version,
- department,
- author,
- access level.
Why?
Because eventually we want the system to say more than:
“The answer is 26 weeks.”
We want:
“According to the Parental Leave section of the Employee Leave Policy…”
Grounding becomes far more useful when the user can inspect the evidence.
11. Step Five: Retrieve the Evidence
Now the user asks:
“Can unused annual leave be carried into next year?”
We encode the question using the compatible retrieval representation and search the index.
Conceptually:
Question
   ↓
Query embedding
   ↓
Similarity search
   ↓
Top relevant chunks
Perhaps the system retrieves:
Chunk A — similarity 0.86
"Employees may carry forward..."

Chunk B — similarity 0.79
"Unused leave exceeding..."

Chunk C — similarity 0.67
"Annual leave balances..."
The exact similarity score is not the answer.
It is a signal used by the retrieval system to rank candidate evidence.
This distinction is important.
Retrieval is itself a prediction problem.
The retriever is effectively predicting:
Which passages are most useful for answering this question?
And like every prediction system, it can be wrong.
12. Step Six: Give the Evidence to the LLM
Once relevant chunks have been retrieved, we construct a prompt.
A simplified version might look like:
SYSTEM:

Answer the question using only the supplied
context.

If the context does not contain enough
information, say that the available documents
do not provide a sufficient answer.

Cite the source used.

CONTEXT:
[leave_policy.pdf, page 17]
Employees may carry forward a maximum of… QUESTION: Can I carry unused annual leave into next year?
Now the LLM generates its response using the supplied evidence.
This is the generation part of Retrieval-Augmented Generation.
13. Why RAG Can Reduce Hallucination—but Cannot Eliminate It
A common description of RAG is:
“RAG fixes hallucinations.”
That is too strong.
RAG can provide relevant external evidence and thereby improve factual grounding. The original RAG research found more factual generation than its parametric-only baseline in the tasks studied [1].
But several things can still go wrong.
Failure 1 — Nothing useful was retrieved
The answer exists in the knowledge base, but the retriever missed it.
Failure 2 — The wrong document was retrieved
The LLM now receives misleading evidence.
Failure 3 — The correct passage was retrieved but ignored
The model may not use the evidence correctly.
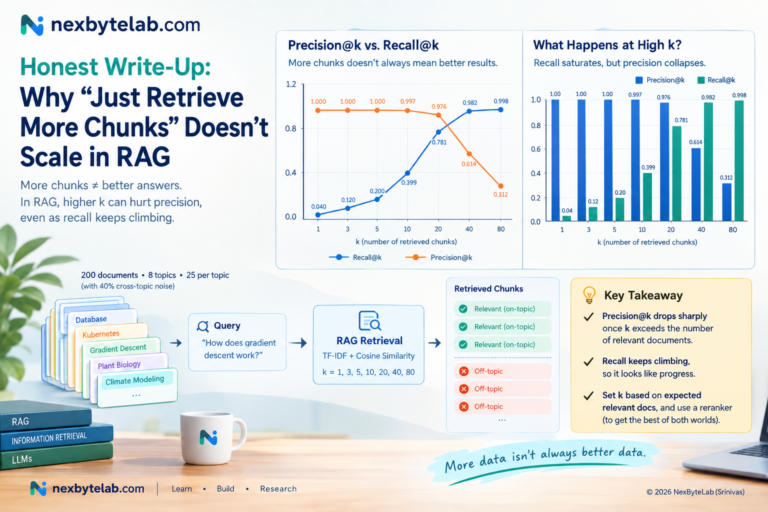
Failure 4 — Too much context was retrieved
More evidence is not automatically better.
Research on long-context language models has shown that their ability to use relevant information can depend on where that information appears in the context [5].
Failure 5 — The model goes beyond the evidence
Even with correct retrieval, a generative model can add unsupported statements.
Self-RAG research specifically notes that conventional RAG does not guarantee that generated output will remain consistent with retrieved passages [4].
Therefore:
RAG changes the hallucination problem. It does not make it disappear.
14. A Minimal RAG Pipeline in Pseudocode
The complete idea can be expressed surprisingly simply.
# INDEXING

documents = load_documents()

chunks = split_documents(documents)

for chunk in chunks:

    vector = embed(chunk.text)

    vector_store.add(
        vector=vector,
        text=chunk.text,
        metadata=chunk.metadata
    )


# QUERY

question = get_user_question()

query_vector = embed(question)

results = vector_store.search(
    query_vector,
    top_k=5
)

context = build_context(results)

answer = llm.generate(
    question=question,
    context=context
)

return answer
Real systems require considerably more engineering, but this captures the core architecture.
Notice something important.
There is no magic RAG algorithm hiding here.
RAG is a system composed of multiple components:
documents + parsing + chunking + embeddings + retrieval + context construction + generation
The quality of the final answer depends on the quality of that entire chain.
15. Is This Already a RAG Agent?
Not necessarily.
This distinction is frequently blurred.
A conventional RAG pipeline follows a mostly predetermined process:
Question
   ↓
Retrieve
   ↓
Generate
   ↓
Answer
It retrieves because we programmed it to retrieve.
An agentic system introduces decision-making about what action should happen next.
For example:
User Question
      ↓
Does this require external knowledge?
      ↓
     YES
      ↓
Search knowledge base
      ↓
Is the evidence sufficient?
      ↓
     NO
      ↓
Reformulate query
      ↓
Search again
      ↓
Enough evidence?
      ↓
     YES
      ↓
Generate grounded answer
Now retrieval is no longer merely a fixed stage.
It becomes an action available to the system.
16. From RAG Pipeline to RAG Agent
Suppose the user asks:
“What is 15 × 17?”
Does the system need to search 5,000 policy documents?
Probably not.
Now suppose the user asks:
“What is our current travel reimbursement limit?”
Retrieval is appropriate.
Now consider:
“Compare our 2025 travel policy with the 2026 policy and tell me what changed.”
The system may need to:
- identify two document versions,
- retrieve evidence from both,
- compare relevant sections,
- detect missing information,
- perhaps search again,
- and then generate a sourced answer.
That begins to look much more agentic.
17. The Research Idea Behind Agents: Reason + Act
One influential framework for thinking about this behaviour is ReAct, introduced by Yao and colleagues and published at ICLR 2023 [3].
ReAct explored combining language-model reasoning with actions that interact with external environments.
Conceptually:
Reason

↓

Act

↓

Observe result

↓

Update plan

↓

Act again
The research showed the usefulness of interleaving reasoning and external actions on question-answering, fact-verification and interactive decision-making tasks [3].
For a RAG agent, an action might be:
SEARCH_DOCUMENTS
or:
RETRIEVE_POLICY
or:
LOOK_UP_DATABASE
or:
SEARCH_AGAIN
The important shift is:
The LLM is helping determine what information-gathering action should occur rather than merely receiving the output of a fixed retrieval pipeline.
18. A Minimal Agent Loop
Conceptually, our RAG agent might behave like this:
while not finished:

    decision = agent.decide(
        question,
        observations
    )

    if decision == "retrieve":

        evidence = retrieve(
            decision.query
        )

        observations.append(evidence)

    elif decision == "answer":

        return generate_answer(
            question,
            observations
        )

    elif decision == "insufficient_evidence":

        return (
            "I could not find enough evidence "
            "in the available sources."
        )
Again, this is intentionally simplified.
The goal is to understand the architecture rather than hide it behind a framework.
19. Why Query Reformulation Matters
Suppose the user asks:
“Can I WFH three days?”
The knowledge base uses the term:
“Flexible Remote Working Arrangement.”
The first retrieval attempt might perform poorly.
An agent could reformulate:
Original query:
Can I WFH three days?

Reformulated query:
remote working policy maximum permitted
days per week
and retrieve again.
This introduces an important difference between fixed RAG and agentic RAG:
retrieval itself can become iterative.
The system can react to the quality of its observations.
20. A More Realistic Architecture
Our complete first RAG agent now looks like:
                USER
                  │
                  ▼
              QUESTION
                  │
                  ▼
          ┌───────────────┐
          │     AGENT     │
          │  Decide next  │
          │    action     │
          └───────┬───────┘
                  │
        ┌─────────┼─────────┐
        │         │         │
        ▼         ▼         ▼
     RETRIEVE   ANSWER   REFORMULATE
        │                     │
        ▼                     │
   VECTOR / SEARCH            │
      SYSTEM                   │
        │                     │
        ▼                     │
     EVIDENCE ────────────────┘
        │
        ▼
    EVALUATE
    EVIDENCE
        │
        ▼
       LLM
        │
        ▼
  GROUNDED ANSWER
        +
      SOURCES
This is much closer to the architecture of a useful knowledge assistant.
21. The Hardest Part of RAG Is Not the LLM
Beginners often assume the most important decision is:
Which LLM should I use?
Sometimes it matters greatly.
But many RAG failures occur before generation even begins.
Consider this pipeline:
Bad PDF extraction
↓
Bad chunks
↓
Poor embeddings
↓
Wrong retrieval
↓
Excellent LLM
↓
Wrong answer
A more powerful generator cannot reliably answer from evidence it never received.
This leads to perhaps the most important engineering principle in RAG:
Evaluate retrieval separately from generation.
22. How Do We Know Whether Our RAG System Works?
Suppose the final answer is wrong.
Where did the failure occur?
There are at least two major possibilities.
Retrieval failure
The system failed to retrieve the evidence needed for the answer.
Generation failure
The correct evidence was retrieved, but the model produced an incorrect or unsupported answer.
These require different fixes.
Changing the LLM may not solve a retrieval failure.
Changing the embedding model may not solve an instruction-following failure.
Therefore evaluation should examine the pipeline component by component.
23. Retrieval Evaluation
Create a small evaluation dataset.
For example:
| Question | Relevant Document |
|---|---|
| How much leave can I carry forward? | Leave Policy §8 |
| Can I work remotely three days? | Remote Work §4 |
| What is the hotel reimbursement limit? | Travel Policy §7 |
Then test whether the correct passage appears among the retrieved results.
Common information-retrieval measures include ideas such as:
Recall@k
Did one of the relevant passages appear within the top k retrieved results?
For example:
Top 5 retrieved chunks

1. Travel booking
2. Hotel reimbursement   ← relevant
3. Travel insurance
4. Meal allowance
5. Taxi reimbursement
The correct evidence appeared in the top five.
That is good retrieval.
It still does not guarantee a good answer.
24. Generation Evaluation
Now evaluate what the LLM does with the evidence.
Ask:
Is the answer correct?
Does it answer the question accurately?
Is it grounded?
Can the claims be supported by retrieved evidence?
Are the citations correct?
Does the cited source actually support the statement?
Does the model abstain appropriately?
When evidence is missing, does it say:
“The available documents do not contain enough information.”
or does it invent an answer?
That final behaviour is especially important in enterprise, research and high-stakes systems.
25. Test the System With Questions It Cannot Answer
This is one of the most useful tests you can perform.
If your knowledge base contains only HR policies, ask:
“What was our company’s revenue in 2024?”
If the documents contain no revenue information, the correct behaviour is not to produce a plausible figure.
It is:
“I cannot determine that from the available sources.”
A RAG system should therefore be evaluated not only on questions it can answer, but also on questions it should refuse or abstain from answering based on insufficient evidence.
That is a much harder—and much more realistic—test.
26. RAG vs Fine-Tuning
These two ideas are frequently confused.
Fine-tuning
Changes the model’s parameters to adapt its behaviour or capabilities.
Conceptually:
Training examples
       ↓
Update model weights
       ↓
Modified model
RAG
Keeps external information outside the model and supplies relevant evidence during inference.
Documents
   ↓
Retrieve
   ↓
Context
   ↓
LLM
If your main requirement is:
“Answer using our frequently changing internal documents.”
RAG is often a natural architecture to investigate.
If your requirement is:
“Change how the model behaves on a task.”
fine-tuning may be relevant.
They are not mutually exclusive.
A system can use both.
27. What RAG Gives You—and What It Doesn’t
RAG offers several attractive properties.
External knowledge
Information does not need to reside entirely inside model parameters.
Updateability
Documents can be added or replaced without necessarily retraining the LLM.
Domain grounding
The system can work with specialised organisational or research material.
Source attribution
Retrieved metadata can support citations and traceability.
But RAG does not automatically provide:
- factual correctness,
- perfect retrieval,
- trustworthy citations,
- causal reasoning,
- secure document access,
- or protection against bad source data.
Those must be engineered and evaluated separately.
28. Security Is Part of the Architecture
Imagine our knowledge base contains:
Employee handbook
and
CEO compensation report — confidential
A user asks:
“How much does the CEO earn?”
A semantic search engine does not inherently understand organisational access policies.
If confidential documents were indexed without proper authorization controls, the retriever may return them.
Therefore enterprise RAG requires more than:
question → vector search → LLM
It also requires considerations such as:
identity
   ↓
authorization
   ↓
permitted documents
   ↓
retrieval
Access control should be enforced at the retrieval/data layer rather than relying solely on a prompt saying:
“Please don’t reveal confidential information.”
29. What Have We Actually Built?
At this point, we understand a system containing:
Document ingestion
↓
Chunking
↓
Embeddings
↓
Search/index
↓
Retrieval
↓
LLM generation
↓
Source attribution
and then an additional control loop:
Decide → Retrieve → Observe → Reformulate → Retrieve again → Answer
The first part gives us a RAG pipeline.
The decision-making loop moves us toward an agentic RAG system.
That distinction is important because not every application needs an agent.
If every question requires exactly one predictable retrieval operation, a simple RAG pipeline may be easier to test, cheaper to run and easier to control.
Agentic complexity should be introduced when it solves a real problem.
30. The Researcher’s View of RAG
A beginner may ask:
“Does my RAG chatbot answer questions?”
A researcher asks something more demanding:
“Under which conditions does this system retrieve sufficient evidence and produce faithful answers?”
That question immediately creates experiments.
Experiment 1 — Chunk size
Test:
128 vs 256 vs 512 vs 1,024 tokens
Measure retrieval performance.
Experiment 2 — Number of retrieved chunks
Test:
Top-1 vs Top-3 vs Top-5 vs Top-10
Measure answer quality, latency and context usage.
Experiment 3 — Retrieval strategy
Compare:
keyword vs dense retrieval vs hybrid retrieval
Experiment 4 — Query rewriting
Compare:
original query vs automatically reformulated query
Experiment 5 — Agentic retrieval
Compare:
always retrieve vs retrieve only when the agent determines external evidence is necessary
Now we have moved beyond:
“I built a chatbot.”
We are conducting RAG research.
31. The Bigger Lesson
RAG is sometimes described as:
“Connect an LLM to your documents.”
That description is convenient but incomplete.
A serious RAG system is an information-retrieval system connected to a generative model.
Its reliability depends on several questions:
Did we ingest the source correctly?
Did we divide it sensibly?
Did we retrieve the right evidence?
Did we rank that evidence appropriately?
Did the model use the evidence?
Did the answer stay faithful to it?
Can the user trace the answer to its source?
Does the system know when evidence is insufficient?
And for an agent:
Did it choose the right action?
That is why building a good RAG agent is less about one clever prompt and more about designing and evaluating an entire system.
Key Takeaways
RAG combines retrieval with generation. It allows an LLM to use external information at query time rather than relying solely on knowledge encoded in its parameters.
Chunking matters. The way documents are divided can influence what the retriever can find.
Embeddings enable semantic retrieval. They represent text numerically so semantically related passages can potentially be matched even when wording differs.
Retrieval is not infallible. The wrong evidence can lead to the wrong answer.
RAG can improve grounding but does not eliminate hallucination.
More context is not automatically better. Language models may struggle to use relevant information reliably in long contexts [5].
A RAG pipeline and a RAG agent are not the same thing. An agent introduces decisions about whether, when and how to retrieve or use other tools.
Evaluate retrieval and generation separately. Otherwise, you may know that the system failed without knowing why.
Citations and abstention matter. A useful knowledge system should show its evidence and recognise when the evidence is insufficient.
The most useful mental model is therefore:
Retrieve the evidence. Evaluate its relevance. Generate from what is supported. Know when you don’t have enough information.
That is the foundation of a trustworthy RAG system.
References
[1] Lewis, P., Perez, E., Piktus, A., et al. (2020). Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks. Advances in Neural Information Processing Systems (NeurIPS 2020). This foundational paper introduced the RAG formulation combining parametric and non-parametric memory and evaluated it on knowledge-intensive NLP tasks.
[2] Gao, Y., Xiong, Y., Gao, X., et al. (2023/2024). Retrieval-Augmented Generation for Large Language Models: A Survey. arXiv:2312.10997. The survey reviews the development of RAG from naive to advanced and modular architectures and discusses retrieval, augmentation, generation and evaluation.
[3] Yao, S., Zhao, J., Yu, D., et al. (2023). ReAct: Synergizing Reasoning and Acting in Language Models. International Conference on Learning Representations (ICLR 2023). ReAct investigates interleaving language-model reasoning with actions that interact with external environments.
[4] Asai, A., Wu, Z., Wang, Y., Sil, A., & Hajishirzi, H. (2024). Self-RAG: Learning to Retrieve, Generate, and Critique through Self-Reflection. ICLR 2024. Self-RAG investigates adaptive retrieval and self-reflection rather than indiscriminately retrieving a fixed number of passages.
[5] Liu, N. F., Lin, K., Hewitt, J., et al. (2024). Lost in the Middle: How Language Models Use Long Contexts. Transactions of the Association for Computational Linguistics. The study demonstrates that language models do not necessarily use information uniformly across long contexts and that performance can depend on the location of relevant information.
Read the Original Research
Lewis et al. — Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
https://arxiv.org/abs/2005.11401
Gao et al. — Retrieval-Augmented Generation for Large Language Models: A Survey
https://arxiv.org/abs/2312.10997
Yao et al. — ReAct: Synergizing Reasoning and Acting in Language Models
https://arxiv.org/abs/2210.03629
Asai et al. — Self-RAG: Learning to Retrieve, Generate, and Critique through Self-Reflection
https://arxiv.org/abs/2310.11511
Liu et al. — Lost in the Middle: How Language Models Use Long Contexts
https://arxiv.org/abs/2307.03172
Next in the RAG Series
Building a RAG System in Python: Documents → Embeddings → Retrieval → Answer
In the next article, we can turn this architecture into a reproducible implementation.
Rather than hiding everything behind a high-level framework, we can build each component separately:
Document → Chunk → Embed → Index → Retrieve → Prompt → Generate → Cite
Then we can deliberately break the system.
We will ask questions with known answers, questions requiring multiple chunks, paraphrased questions and questions for which the knowledge base contains no answer.
Finally, we can measure:
Recall@k → Answer Correctness → Groundedness → Citation Accuracy → Abstention
That will allow us to answer a much more meaningful question than:
“Does my RAG demo work?”
We can ask:
“How do we know that it works?”
Follow-up experiment: we ran a small, reproducible test on one of the pipeline decisions above — see How Much Does Chunk Size Really Affect RAG Retrieval?
Related Reading
- How Much Does Chunk Size Really Affect RAG Retrieval? — a deep dive on one of the pipeline decisions made here
- Benchmarking Open-Source LLMs: A Practical Comparison — choosing the model that powers this pipeline